Introducing Ad Blocker for Firefox on iOS: More Control, Fewer Distractions
There’s only so much room on your screen. Pop-ups, overlays, and ads can take over fast, getting between you and what you came to do.
That’s where Ad Blocker for Firefox on iOS comes in: a built-in option that blocks many third-party ads and ad-related trackers before they load, helping reduce clutter and distractions while you browse.
How it works
Ad Blocker uses Apple’s WebKit Content Blocker technology and the EasyList filter list to determine what gets blocked. There’s no separate extension to install, and you can turn it on in Settings > Browsing > Ad Blocker. It’s off by default, so you decide whether to use it.
Ad Blocker won’t block every ad. Ads served directly by the site you’re visiting and ads shown in search results will still appear. Sponsored shortcuts and other sponsored content shown by Firefox when you open a new tab are separate from ads on the web pages you visit, so Ad Blocker doesn’t affect them.
Ad Blocker works alongside the privacy protections already built into Firefox, including Enhanced Tracking Protection, which blocks many trackers and limits tracking across the web.
More control over how you experience the webOn Desktop and Android, Firefox already supports a strong ecosystem of ad-blocking and privacy extensions, giving people the flexibility to choose the tools that work best for them. We value that ecosystem and will keep supporting it.
iOS works differently. Extensions aren’t available in the same way, and we know people want more options. Bringing ad blocking to Firefox on iOS meant building it directly into the browser.
Giving people choice in how they experience the web is important to us. Advertising helps fund much of the open web, supporting the publishers, creators and websites people rely on. We also know that ads can sometimes crowd the screen or interrupt what you’re trying to do.
That’s why Ad Blocker is optional: you decide whether it’s part of how you browse. It’s part of a broader approach across Firefox to give you more control over your experience, from the extensions you use to how AI shows up in your browser.
Try itTo turn on Ad Blocker, go to Settings > Browsing > Ad Blocker.
If you find an ad you expected to be blocked, a site that behaves strangely or something we should improve, let us know on Mozilla Connect.
Visit our Support page for more details on Ad Blocker for Firefox on iOS. For more on Firefox’s built-in privacy protections, check out How Firefox Protects Your Data.
The post Introducing Ad Blocker for Firefox on iOS: More Control, Fewer Distractions appeared first on The Mozilla Blog.
A New Framework for Open Source AI
Open or closed AI isn’t a fringe question anymore; it’s a live policy debate, with real consequences for who gets to build, audit, and compete in the AI ecosystem. But as that debate plays out in Washington, Brussels, and beyond, the harder questions are still very much up for discussion. What does meaningful openness actually require? Where should the guardrails sit? And who gets a say in setting them?
That’s exactly the gap a group of us set out to close two years ago.
Back in 2024, Mozilla and the Columbia Institute of Global Politics brought together more than 40 researchers, builders, and policy experts for the Columbia Convening on Openness and AI. The goal was simple to state, but hard to do: figure out what “open” actually means once you’re talking about foundational models rather than traditional software, and build a shared vocabulary that researchers, developers, policymakers, and civil society could all work from.
The convening was the start of a years-long effort to turn a room full of perspectives on openness into something durable and useful for developers, builders, and policymakers alike. Recently, that effort reached a new milestone: Communications of the ACM published “Unpacking Open Source AI: Toward a Framework for Openness in Foundation Models,” which I co-authored alongside a host of other allies spanning academia, industry, and civil society.
The paper outlines a framework that does something the open source AI debate badly needs. It stops treating “open” as a single switch you flip on or off. Instead, it breaks the AI stack down into its component parts – data, code, model weights, documentation, and more – and looks at how openness at each layer shapes who actually gets to inspect, use, and build on a system. That kind of specificity matters. A lot of the current policy debate treats open source AI as a monolith, when in reality the details of what gets shared (and how) are what determine whether openness delivers on its promise of safety, competition, and accountability.
A few of the framework’s ideas are worth pulling out. First, it treats openness as a gradient rather than a binary. A system can be open on weights while remaining closed on training data, or open on code while offering little documentation on how it was evaluated. The framework offers language to describe that mix precisely, instead of lumping it under one vague label. Second, it argues that safety can’t be assessed at the model level alone: what matters just as much is the surrounding system – the deployment environment, the safeguards, the moderation layers, and governance structures. That’s because a model’s real-world risk profile is shaped by all of it together, not by the weights in isolation. Critically, the framework deliberately stops short of prescribing one “correct” level of openness for every system. Instead, it gives developers, researchers, and regulators a common vocabulary to make and evaluate those tradeoffs on a case-by-case basis.
It’s worth pausing on who’s behind this work. Scroll through the author list, and you’ll find a genuine cross-section of the individuals and organizations contributing to moving the development of open systems forward. It’s a collection of people who’ve spent years arguing, in good faith and often across real disagreements, that open approaches can be a foundation for safer, more democratic, more accountable AI. That’s the same spirit that drove the original convening, and it’s what makes this paper a genuinely important milestone for our mission to make AI systems accessible to the many, rather than the few.
You can read the full paper here.
The post A New Framework for Open Source AI appeared first on The Mozilla Blog.
The wait is over. NVIDIA GeForce NOW adds Firefox to its supported browser lineup.
Gamers have asked for GeForce NOW support for years. Today, NVIDIA made it official, opening up GeForce RTX-powered play to Firefox on Windows.
Firefox users can now stream more than 2,000 PC games from virtually anywhere, no downloads, installs, or hardware upgrades required, just a Windows PC and a browser.
Gaming: one of the web’s toughest testsCloud gaming pushes a browser in ways most websites never do. Every click and frame matters. Behind today’s announcement is months of collaboration and engineering between Mozilla and NVIDIA to deliver GeForce NOW on Firefox for Windows.
Now, players can jump into high-performance PC gaming directly from Firefox, no waiting on lengthy game downloads, installs, or updates. The experience delivers GeForce RTX-powered performance at up to 1440p and up to 120 frames per second for GeForce NOW Ultimate members.
“Firefox earned its place on our list of supported browsers by delivering the first-class experience GeForce NOW players expect. We set a high bar for browser support, and we’re excited to welcome Firefox — giving millions of Firefox fans a new way to stream the games they love,” said Andrew Fear, Director of NVIDIA GeForce NOW.
 Versatility and customization baked into your gaming rig
Gamers put real effort into making their rigs their own, and Firefox gets that. Users can choose themes, custom colors, and tab settings to customize their setup, instead of sitting there like just another window.
We also know online gaming doesn’t happen in just one window. It’s social and sometimes spontaneous. With Firefox, you can have a Discord call running in Split View, a guide open in another tab, or Reddit pulled up between matches. Then go full screen when you’re ready to play, no need to switch browsers to stream games.
“Teaming up with NVIDIA to bring GeForce NOW to Firefox is a milestone moment — one of the world’s leading cloud gaming services, now running on a browser built for privacy, control and flexibility. This is a big win for the Firefox community and for NVIDIA’s gaming community — and a sign of even bigger things ahead,” said Ajit Varma, Head of Firefox.
If Firefox is already your browser of choice, online gaming and your PC game library can join the party. Whether your library lives on Steam, Epic Games Store, GOG, Xbox PC Game Pass, or Ubisoft Connect, you can sign in, open your library, and start streaming the games you already own. For all the gamers returning to Night City in Cyberpunk 2077, jumping into Halo: Campaign Evolved, or dropping in for a quick round of Fortnite, Firefox users can now play where you want.
Update to the latest version of Firefox, go to play.geforcenow.com, and sign in with your GeForce NOW account.
Join us August 25 as NVIDIA heads to Gamescom, where we’ll have more to share about what this partnership means for gamers.
The post The wait is over. NVIDIA GeForce NOW adds Firefox to its supported browser lineup. appeared first on The Mozilla Blog.
A billion searches a year, now built in: Startpage comes to Firefox
Firefox users were choosing Startpage long before today — to the tune of more than a billion searches a year, every one of them required some assembly: an extension, a manual setting, a workaround.
Today, starting with Firefox 154, that choice becomes as easy as head to the drop-down menu, hit ‘select,’ and start searching. Startpage is now a built-in search option for Firefox users on desktop in Germany, France, Austria, Switzerland, and the Netherlands. Android and iOS are coming soon. Whether you want to search with Startpage, or another preferred search engine, it’s as easy as opening your search settings, picking a default, and done.
And if you’re happy with your current search engine, nothing about your setup changes.
Why Europe firstThis launch starts in Startpage’s home markets: a Netherlands-based search engine, now built into the browser for some of the most privacy-conscious users in the world. At a moment when so much of the web experience is decided by a handful of very large companies, a search option that’s private by design and European by origin isn’t a small thing.
What Startpage deliversStartpage delivers full, high-quality search results without the privacy trade off. Queries aren’t stored or linked to you, and there are no AI answers pushed above your search results. In fact, there’s no AI at all. Based in the Netherlands, Startpage built its product around a simple idea: great search and personal privacy can go hand in hand.
“So much of your web experience is prescribed before you ever open a browser. We’d rather you decide how you want to search. Adding Startpage puts a genuinely private search engine option — real results, zero profiling, AI-free — one click away for millions of people in Europe,” said Ajit Varma, Head of Firefox.
Users asked with one billion searchesStartpage ranks among the most-requested search engines in the Firefox community. When demand is this clear, our job is to remove the friction.
“More and more of what people use online comes from a handful of very large companies, and search is where that concentration gets felt most directly. Firefox has always been the browser for people who want to make their own decisions about the web, which makes it a natural home for private search. Firefox users already run over a billion Startpage searches a year. Now Startpage is built in for everyone in these markets,” said Stewart Marlborough, President of Startpage.
That’s the pattern we want: people who use Firefox every day tell us what they need, and we ship it.
Search is a choice. Firefox treats it like one.Most browsers have already decided how you’re going to search. Firefox hasn’t. Pick your search engine, control what happens to your queries, decide who sees data about you, even turn AI on or off. It should always be your call. Not everyone wants the same thing from search, and a browser shouldn’t pretend they do.
Try it outIf you’re in Germany, France, Austria, Switzerland, or the Netherlands, update to Firefox 154 and you’ll find Startpage in your search settings.
The post A billion searches a year, now built in: Startpage comes to Firefox appeared first on The Mozilla Blog.
Smart Window: Finish what you start online
Update on September 16, 2026: Smart Window is now rolling out in France, marking its first expansion beyond North America. People in France will be able to download and try the Smart Window beta in French. Download Smart Window here and share your feedback with us on Mozilla Connect.
Original post from August 2026:
Browsers make it easy to start things, but picking them back up is another story.
We start planning a trip or researching a purchase, and before long we’re comparing options and chasing ideas across dozens of tabs. That work rarely happens in one sitting. When we come back after an interruption, we have to figure out where we were, what we’d already found, and what we were trying to do in the first place.
Smart Window is Firefox’s privacy-first, AI-powered browsing experience designed to help people finish what they start online. It works with the context you choose to share, such as your open tabs and relevant browsing history, so you can get back to what you were doing without retracing your steps.
We’ve spent the last several months building and testing Smart Window in beta with our community. Today, we’re adding new capabilities that help you check answers without losing your place, make sense of open tabs and get back to things you’ve seen before. Together, they help keep a task moving across tabs, searches, and time.
“The browser already has much of the context around what you’re trying to do — the research in your tabs, the pages you’ve visited, the things you’ve found along the way,” said Ajit Varma, Head of Firefox. “With Smart Window, we’re exploring how to make more of that context useful while keeping you in control.”
What’s new in Smart Window Check answers without losing your place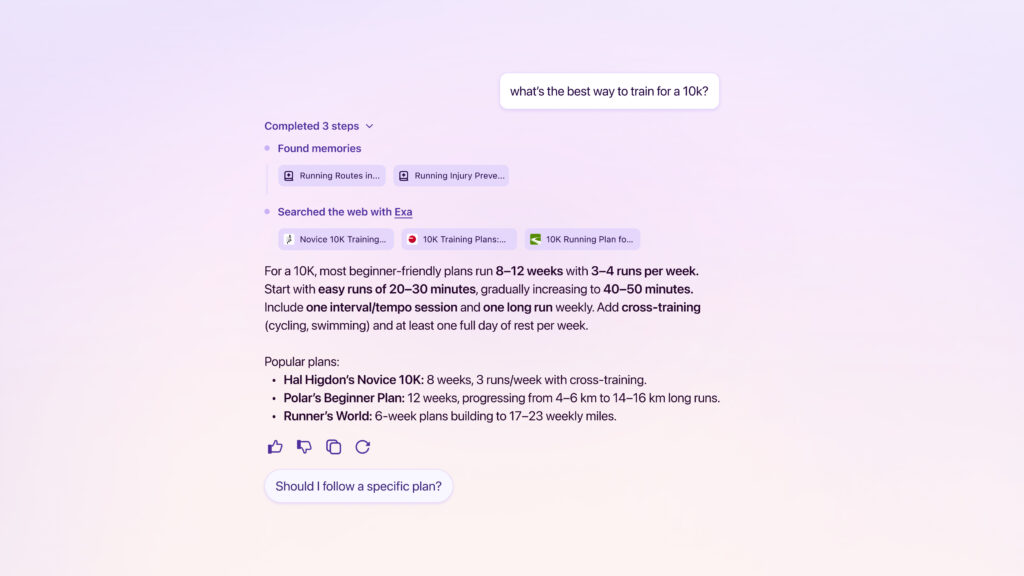
When you have a question in the middle of a task, getting an answer shouldn’t take you out of your flow or require you to track down the sources separately.
Through our new partnership with Exa, Smart Window can now retrieve current web information and show the sources behind its response without taking you to a separate search results page. Learn more about why we chose Exa and what the partnership means for Firefox in our companion post.
Group tabs that belong together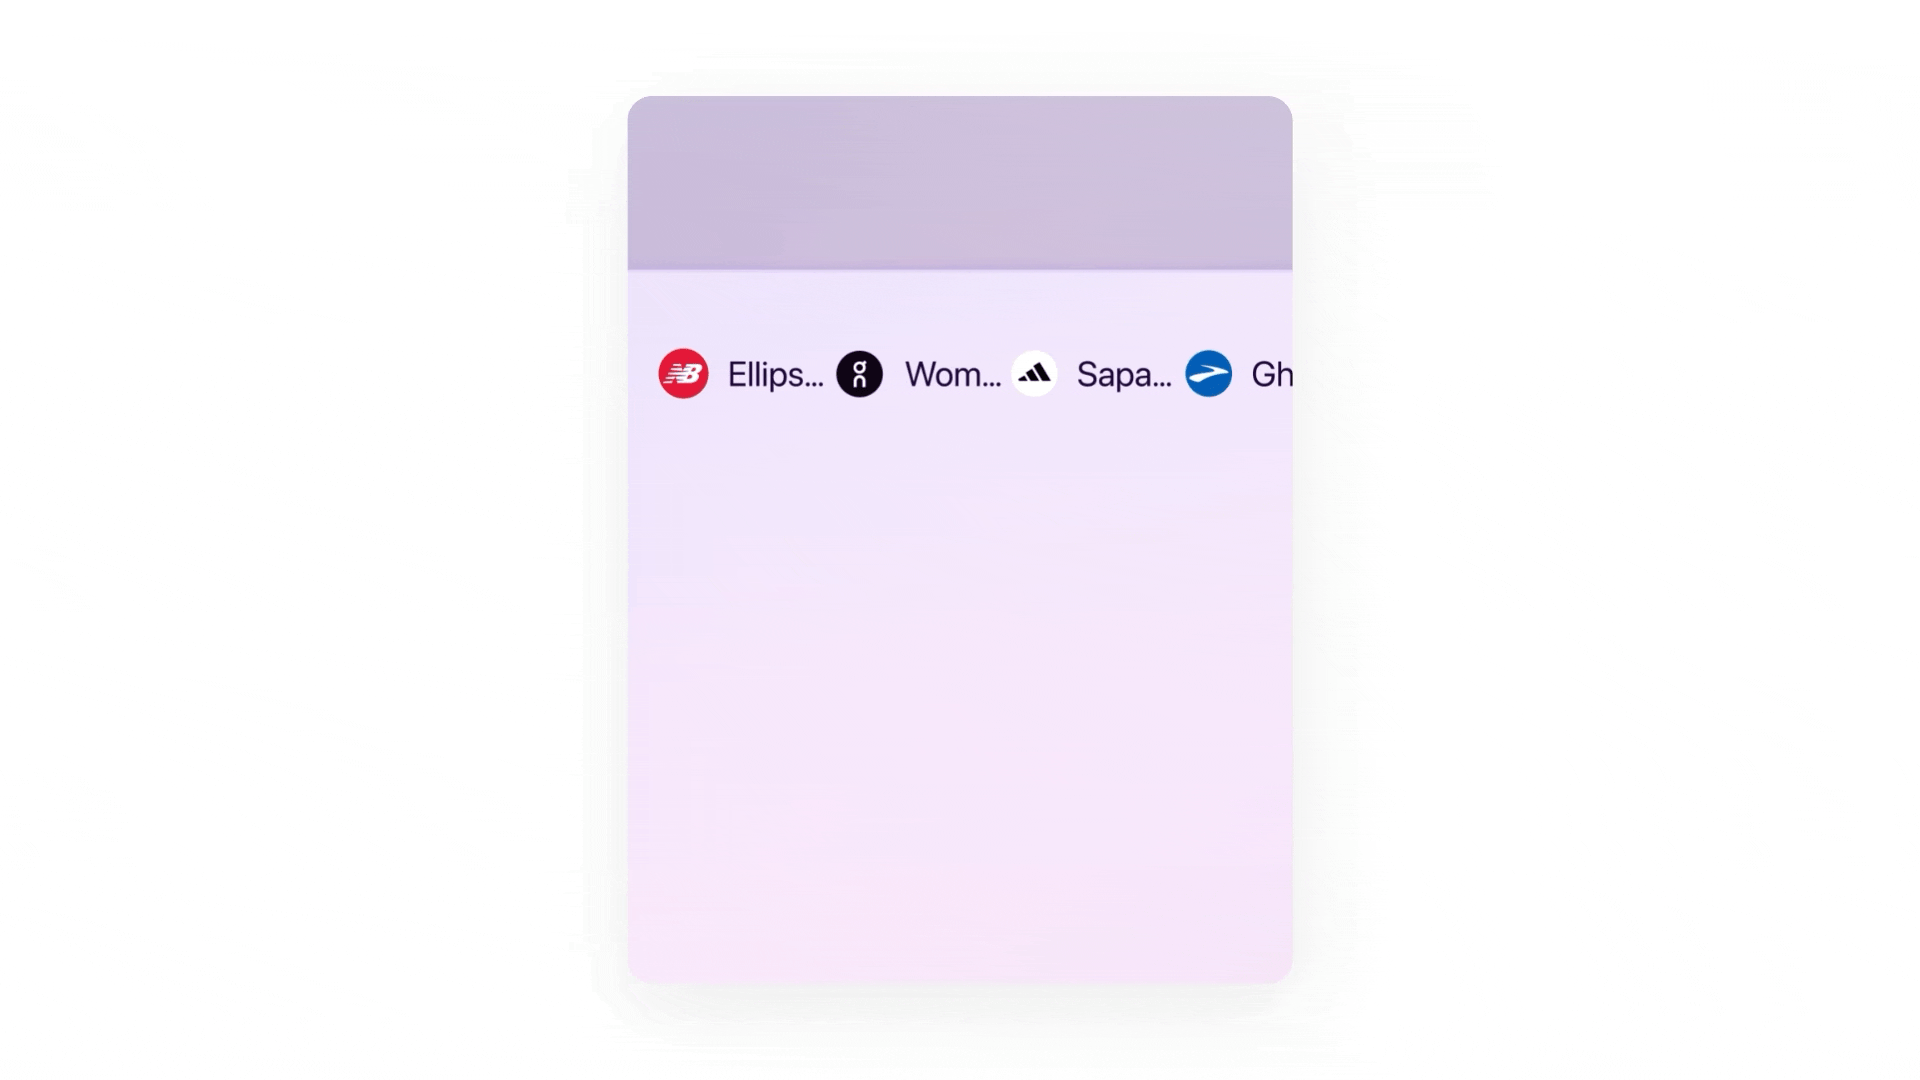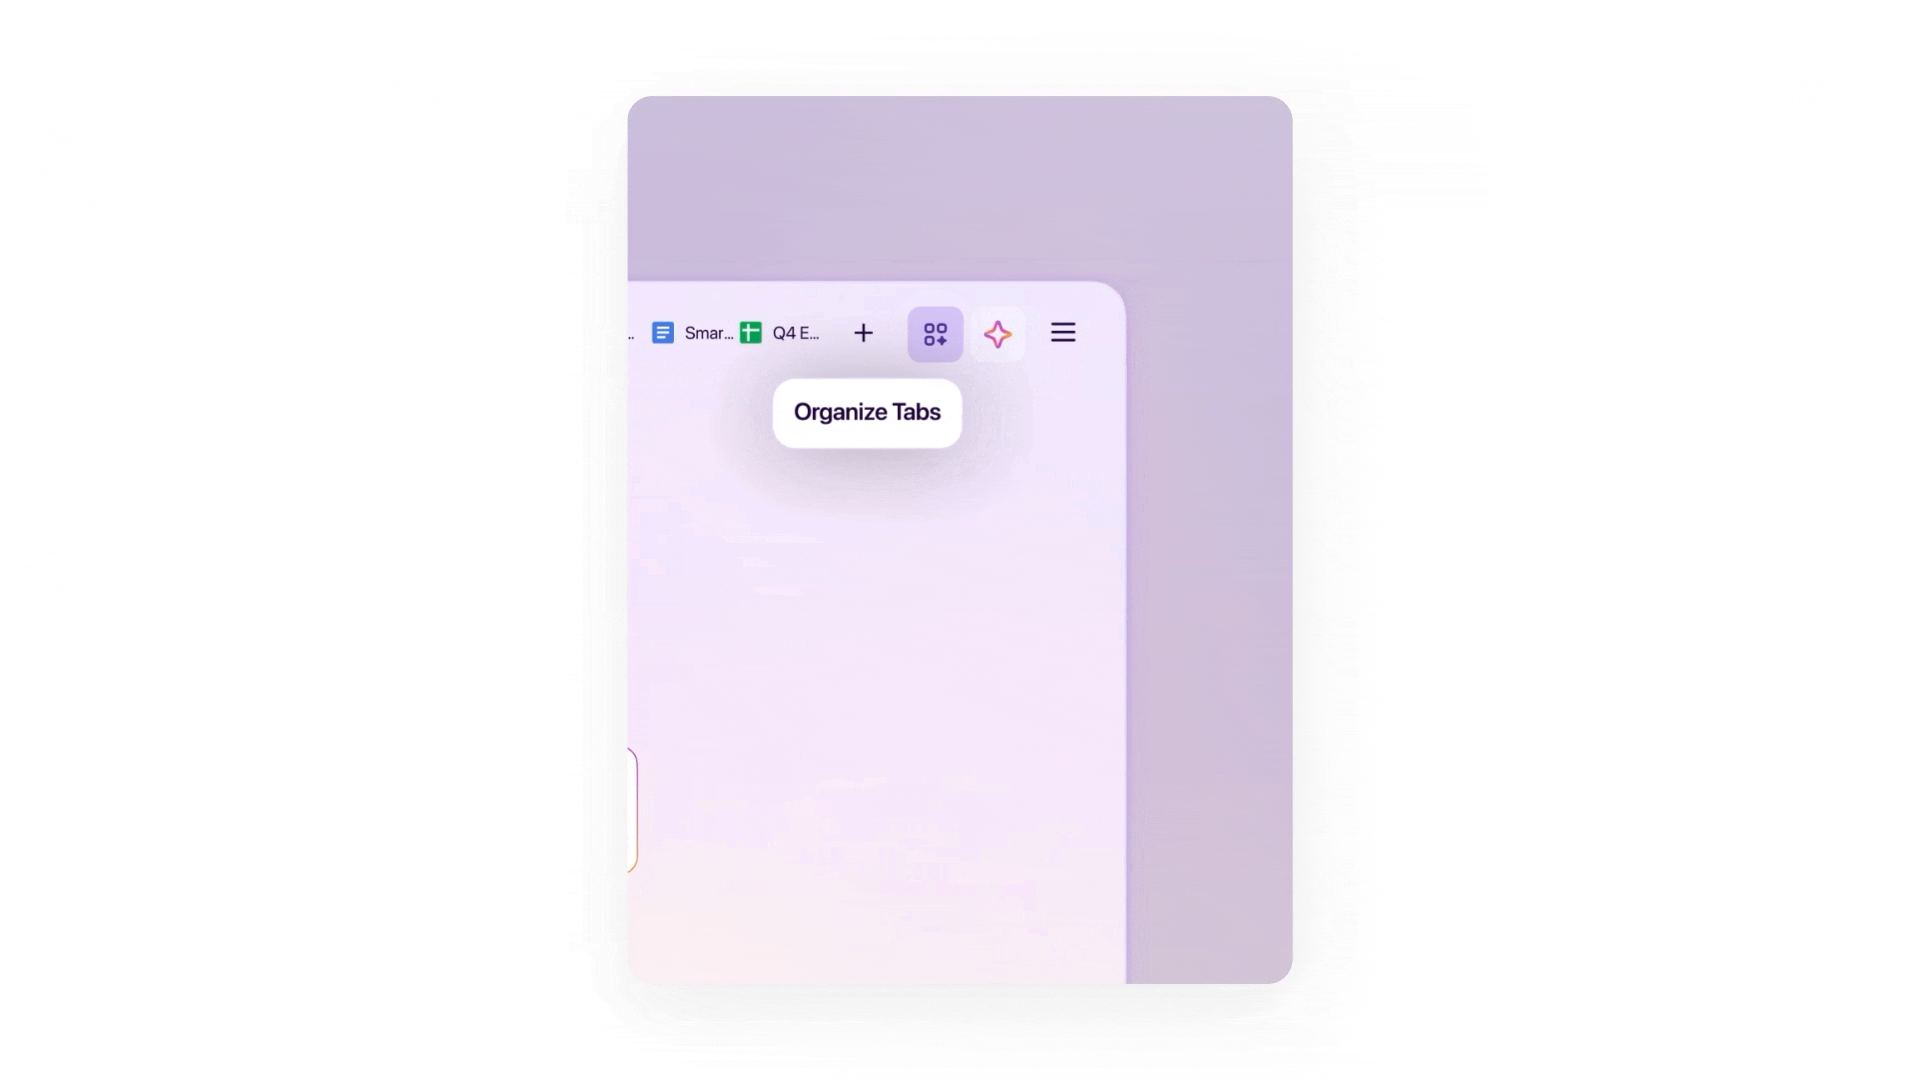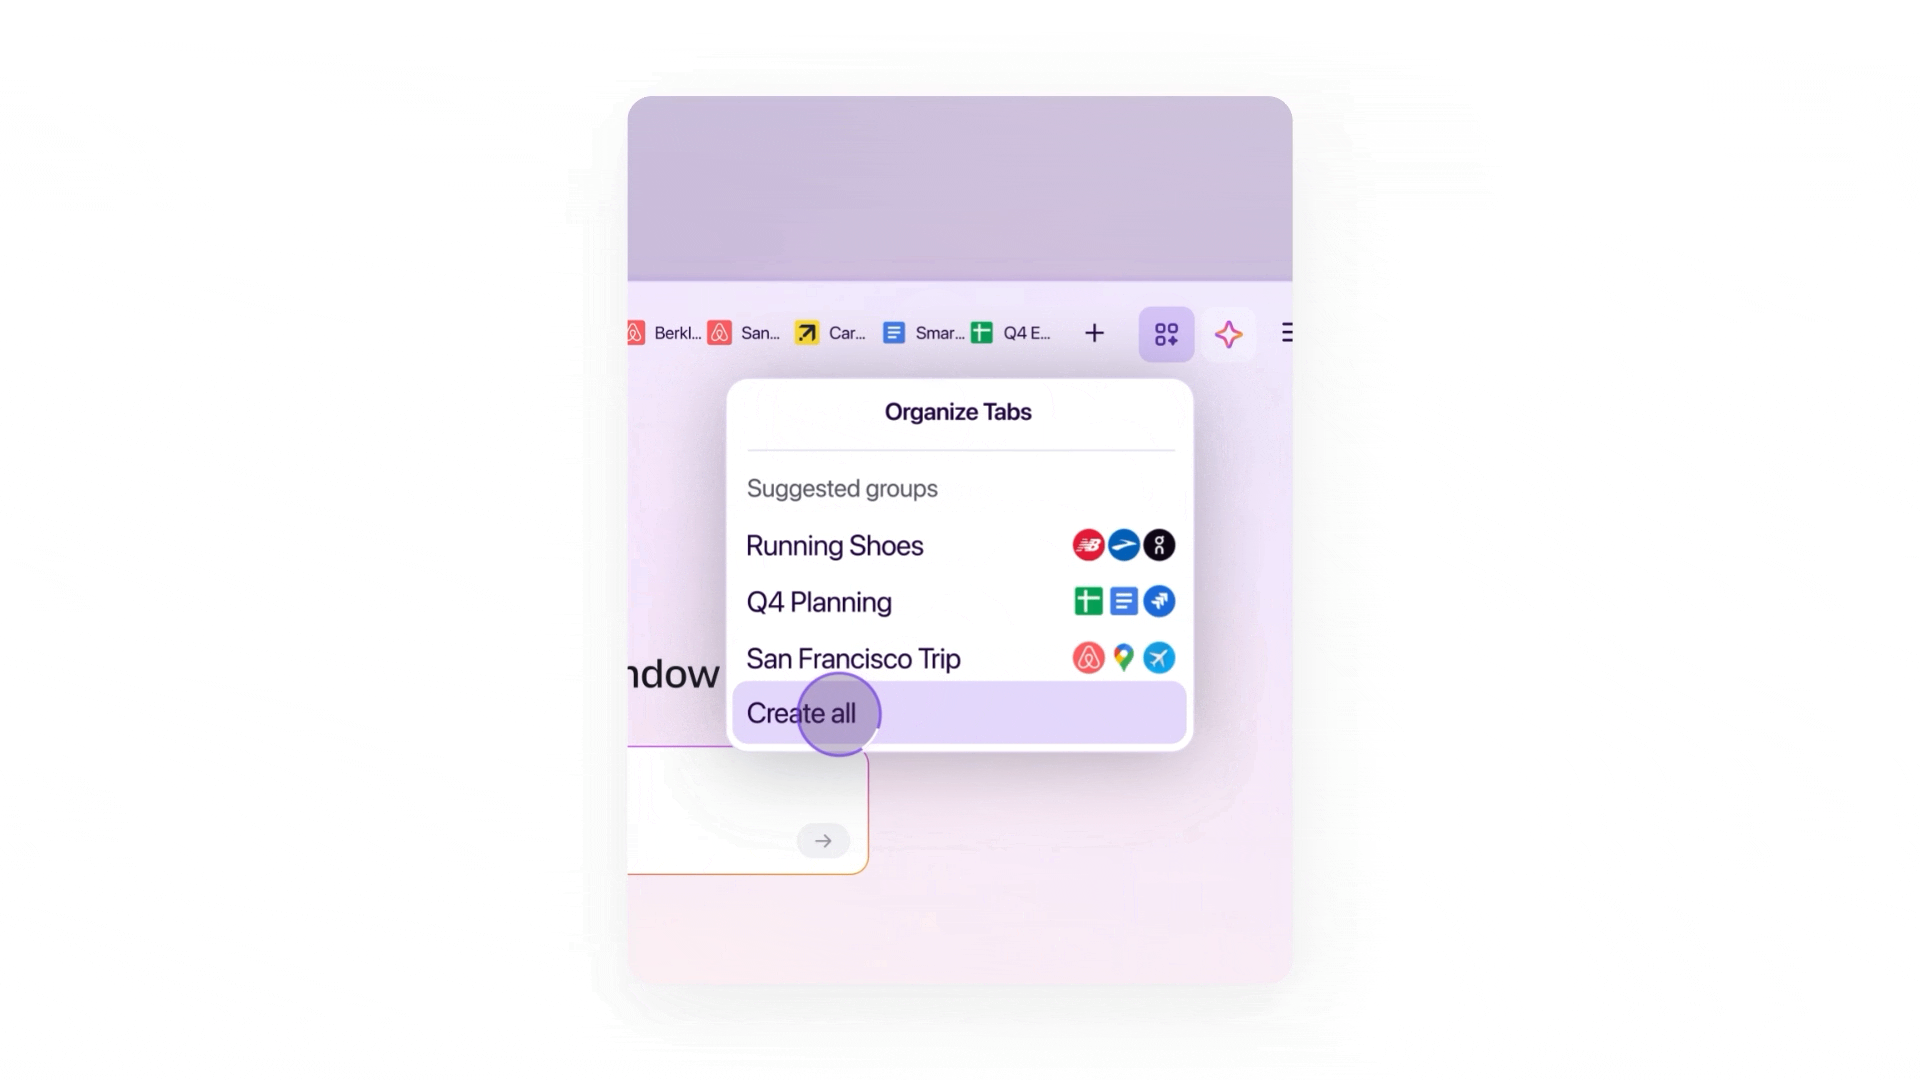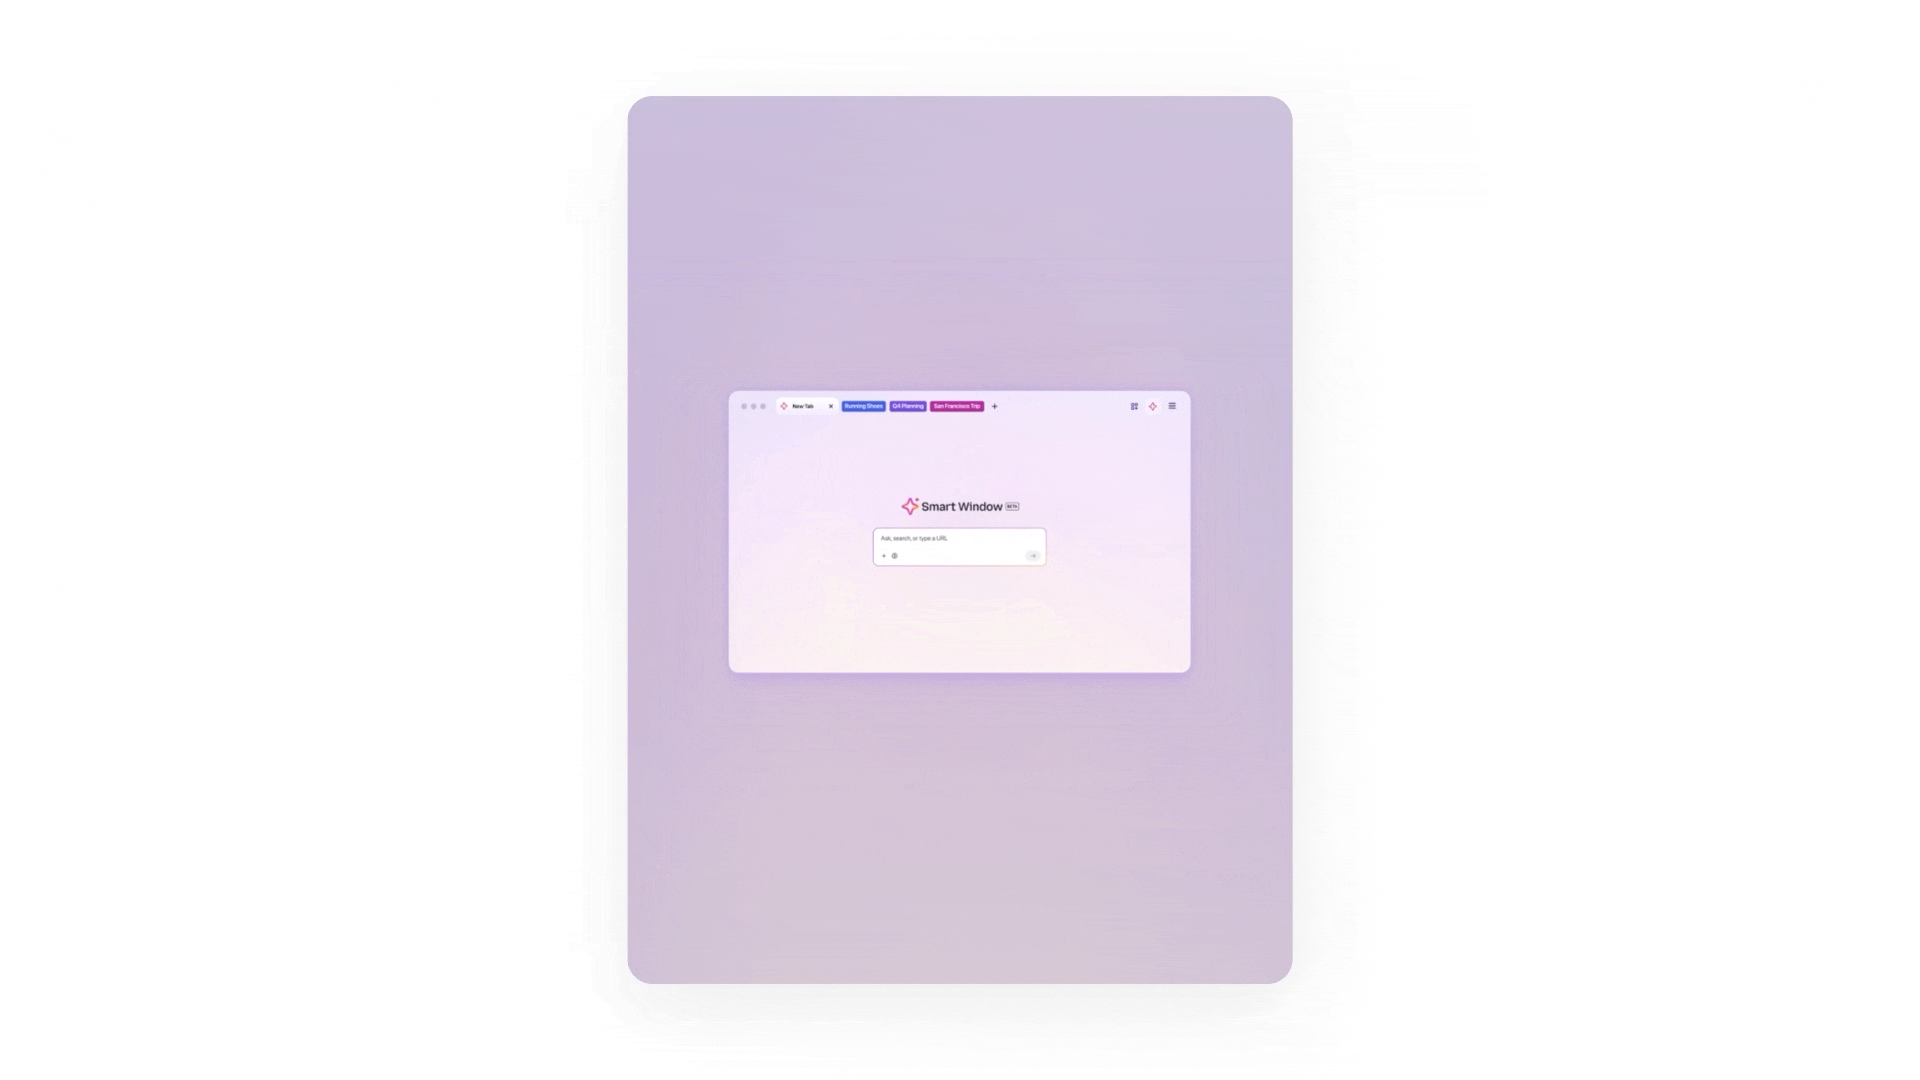
It doesn’t take long for a quick search to turn into a browser full of tabs. Once they pile up, keeping track of everything becomes even more work.
Smart Window can now suggest groups for related tabs, making it easier to organize what you have open and return to it later. It can also spot duplicate tabs and close them with a click.
Find your spot again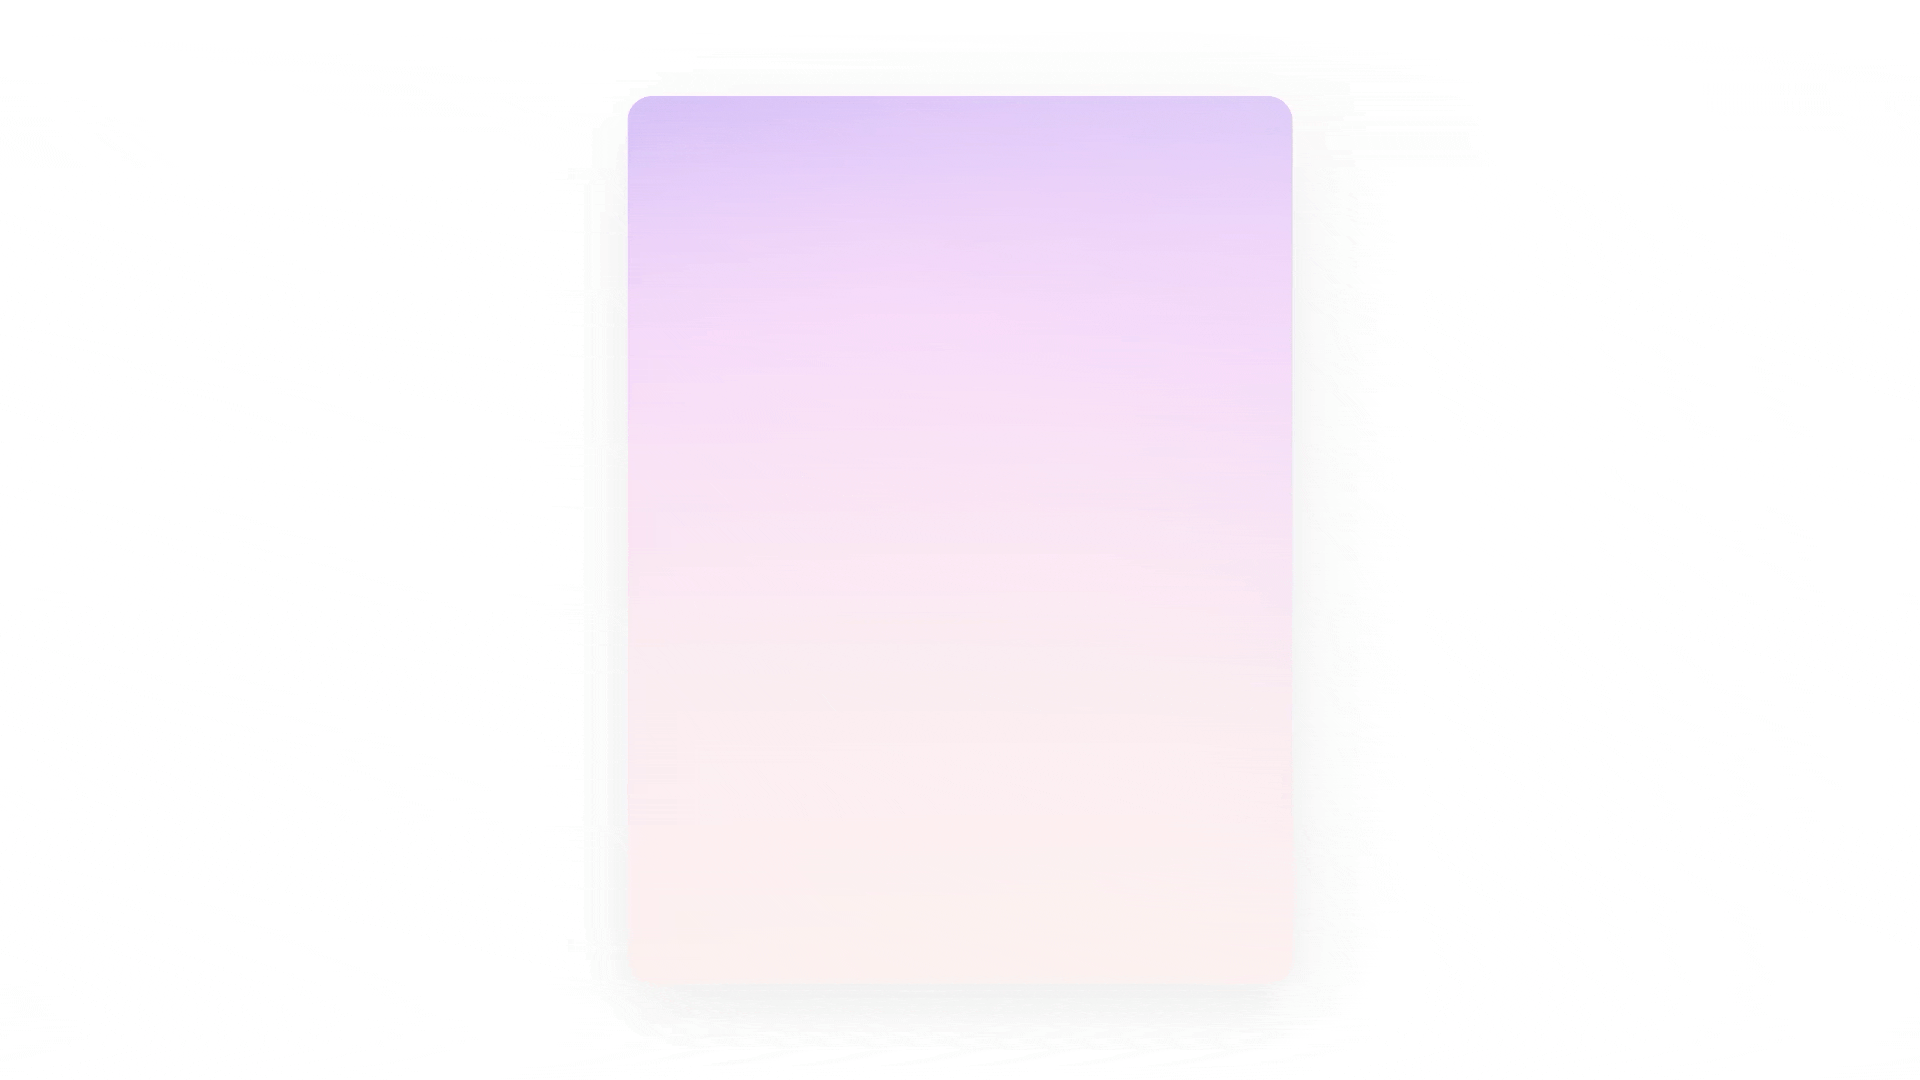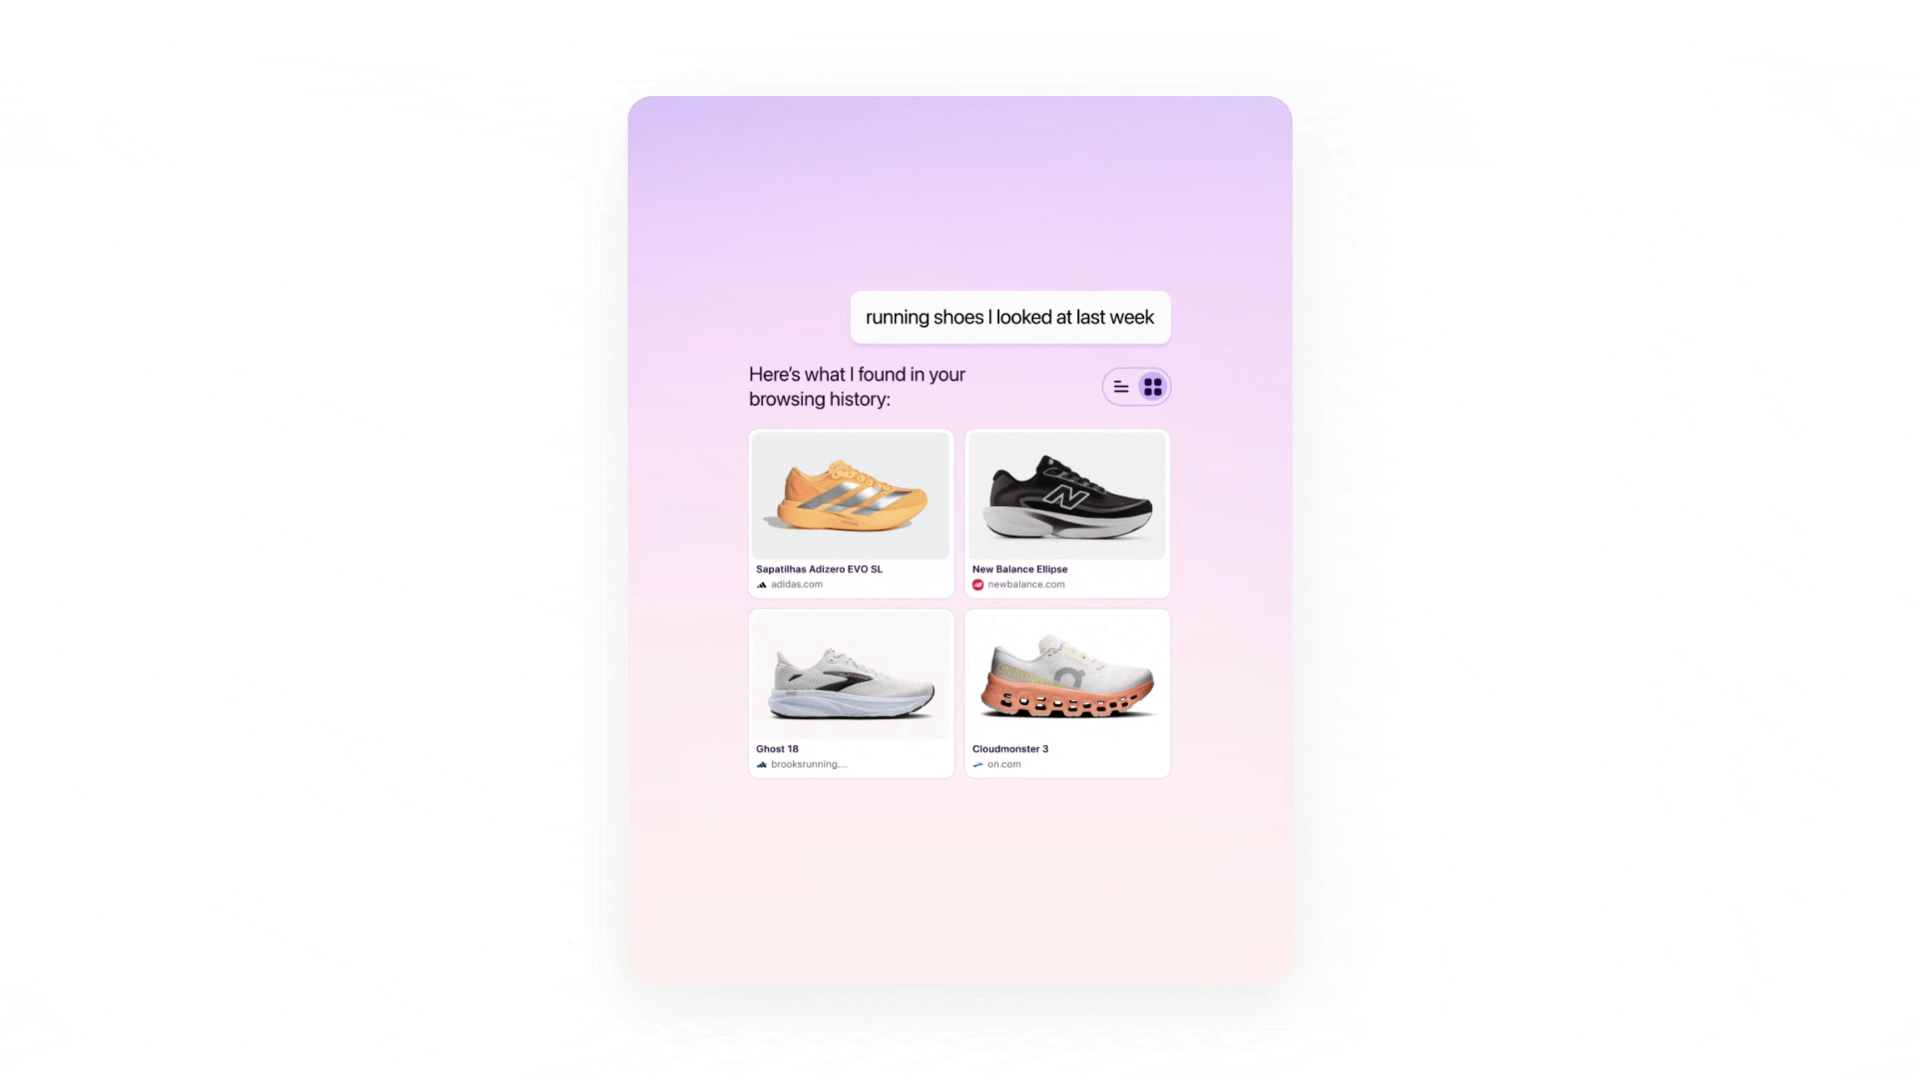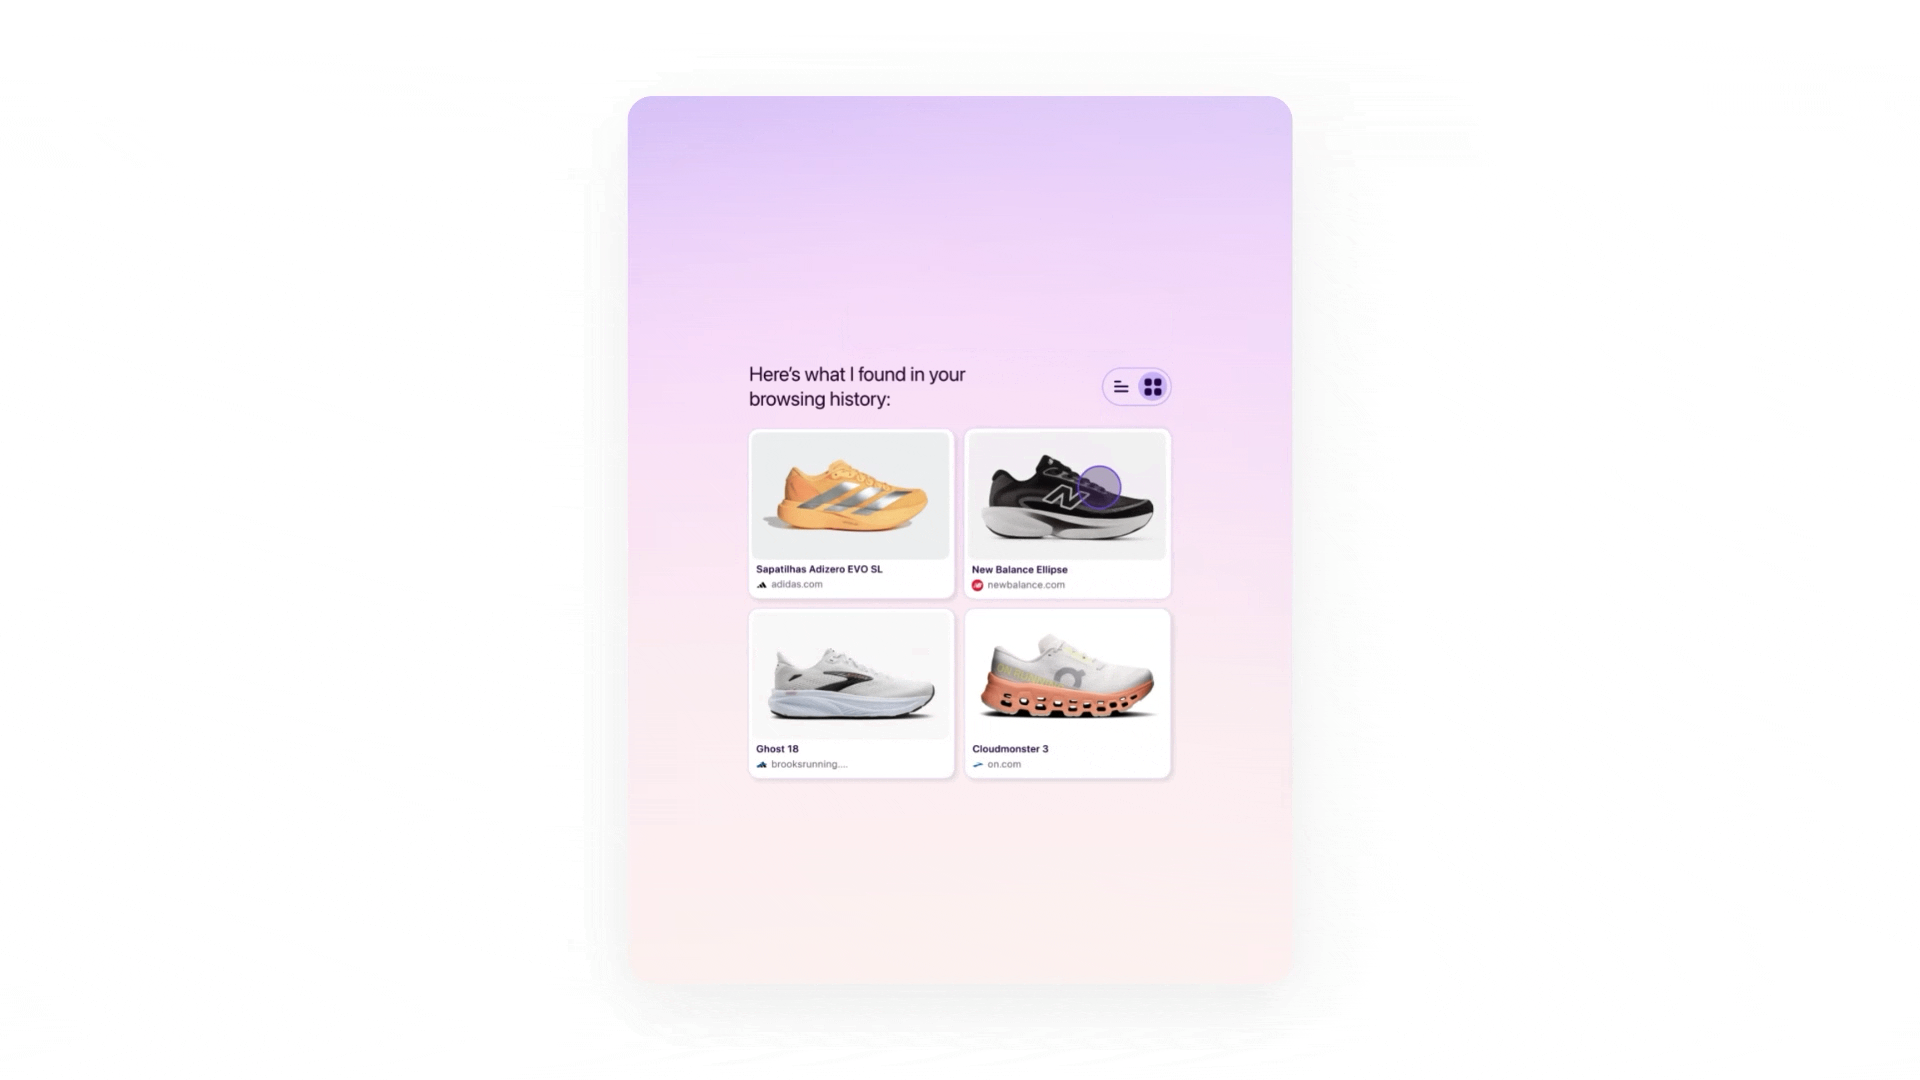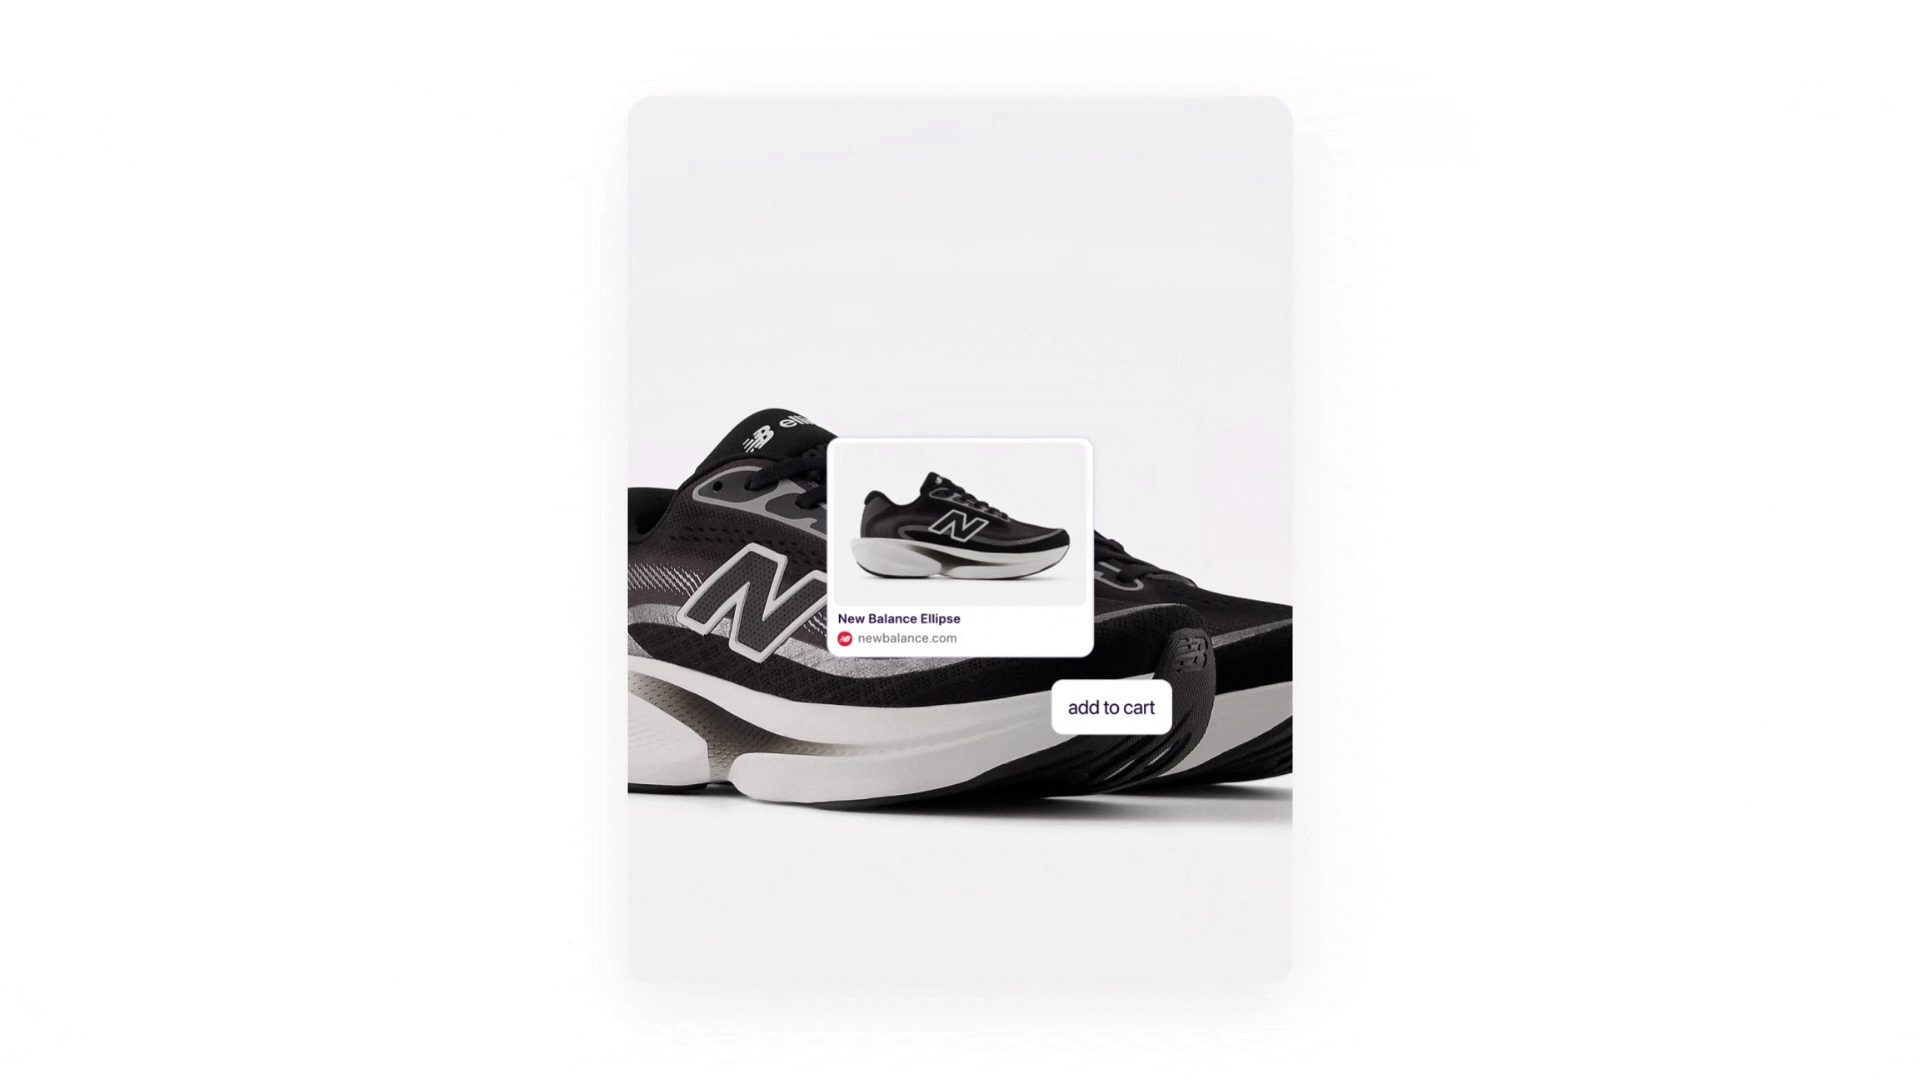
Sometimes you remember what was on a page better than you remember what it was called or how you got there. Smart Window can now show visual previews of pages in your browsing history, making it easier to spot the page you’re looking for among similar results without opening each one to figure out which is which.
Behind the evolutionLast November, we shared an early concept called “AI Window,” exploring what it could look like to give people a user-controlled space where they could chat with an AI assistant to get help while browsing. We shared it early because we wanted our community to help shape where it went next.
Over the months that followed, we watched how people used the experience, listened to feedback, and tested new ideas. A consistent theme emerged: people were increasingly using it as part of their everyday browsing — searching, navigating, and working through the things they’d come online to do. The value of the AI assistant came through in how it helped them make progress on those tasks.
We saw the same idea in feedback from beta users. One described using Smart Window to keep track of their “train of thought.” Another used it to find something they’d looked at before without remembering exactly where they’d seen it.
Those learnings helped us shape Smart Window into a broader browsing experience that helps people make progress on what they came online to do.
While the product is evolving, the principles we started with remain the same: choice, privacy, and transparency. Smart Window is optional. You choose when to use it, what browsing context it can use to help with a task, and which AI model you want to use. Firefox’s AI Controls gives you one place to manage Smart Window, including turning it off entirely, so you can easily choose the browsing experience you want.
What’s nextWe’re continuing to explore ways Smart Window can help carry a task forward, especially when you leave it and come back later.
Soon, Smart Window will be able to surface recent browsing journeys and pull together related tabs and history, giving you a starting point when you return to something you were working on. We’re also working on ways for Smart Window to use relevant information to help fill out online forms, so you don’t have to re-enter the same details again and again. You’ll stay in control of what Smart Window can access, including which tabs you choose to share with it.
Smart Window remains in beta, and we’ll keep learning from our community as these experiences develop. It’s currently available in English to people in the U.S. and Canada. If it’s not available where you are yet, you can sign up to be notified when it is.
To try Smart Window, visit https://www.firefox.com/smart-window.
The post Smart Window: Finish what you start online appeared first on The Mozilla Blog.
Firefox and Exa: Building AI search around people, not platforms
AI has changed how we browse. Full stop. The real question is whether AI leads to one browser experience for everyone, or gives people more ways to make the browser work for them.
Firefox was always built to give users an alternative to the status quo, and our approach with AI is no different. Much of the industry is going in another direction: Company A builds the browser → and the search engine → and the AI model → and all the surrounding services. The seduction lies in how effortless every layer feels, but it also means one company has total influence over what tech you can use and what AI delivers.
We aim to deliver users a different model: one where AI makes your browser empowering and helpful, with visible citations and with a zero-data-retention commitment, all powered by an independent browser engine. To get there, we’re partnering with people who align with the same open, choice-first thinking that’s shaped Firefox from day one.
Today, that starts with Exa.ai, a search and retrieval company built for the AI era.
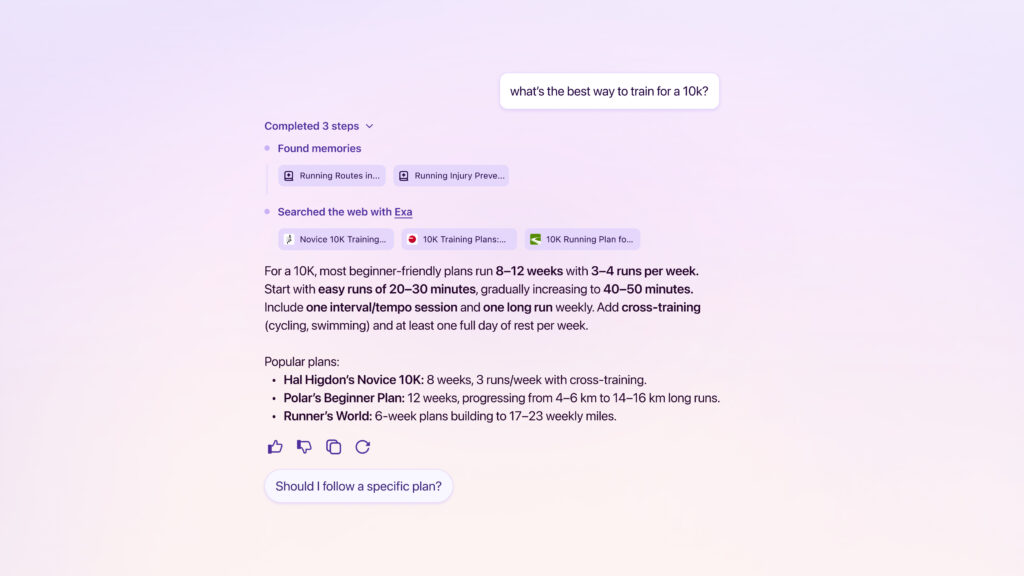
Going forward, Exa will help power Smart Window on desktop and Quick Answers on iOS, giving people a way to get current, source-backed answers without leaving the page. More on our related Smart Window announcement here.
But our Exa news isn’t about one feature or product. It’s about model choice and how people find things online.
 An independent AI model
Mozilla has always believed the web is strongest when it encourages technology competition and variety, and we think the same principle should apply to AI. We want to create an AI ecosystem that is open, diverse, and grounded in the same values we champion for the web. So, instead of building our own closed AI stack, Firefox is investing in partnerships with companies like Exa.ai to bring deep expertise in specific areas while sharing our commitment to user choice, privacy, and transparency.
As Ajit Varma, Head of Firefox, puts it, “Firefox’s philosophy is straightforward: the open internet is a critical resource and people should be able to shape it to their needs and preferences — even as new entry points like AI emerge. AI should be responsible. It should stay transparent and under your control. AI shouldn’t be an-all-or nothing offering, but rather built so users can pick and choose the model or system that works for them.”
The idea is simple: Mozilla builds the browser people trust, and partners like Exa.ai bring the specialized pieces that make it better. That lets us move faster without asking people to give up what made Firefox different in the first place.
Adds Will Bryk, Co-founder and CEO of Exa.ai, “Search built for the AI era doesn’t work if it’s locked inside one company’s stack. Firefox is one of the last browsers that isn’t trying to own the model, the search, and the browser all at once. That’s why this partnership makes sense to us. We’re building the information layer for an agentic web, where trust and transparency are paramount. We share those values with Firefox, making this partnership a very easy call.”
AI should make the web more useful, not replace itAI is only as useful as your ability to check its work.
That’s the point of building Exa’s retrieval into Firefox: when you get an answer, you can see the source it came from. Nothing is buried in a ‘citations’ menu, but sitting right there so a two-second glance tells you whether to trust it or read more. We’re not forcing you ‘just trust us’ that it’s right.
It’s a small design choice, but it matters. It’s the difference between an AI that tells you things and one that shows you where to look. It also means the people who actually wrote that content don’t disappear from the picture, the way they often do when AI summarizes and moves on.
Looking aheadThis won’t be the last partnership like it. We’re picking partners for the same reason each time: people who think AI in a browser should work for you, not the other way around.
The post Firefox and Exa: Building AI search around people, not platforms appeared first on The Mozilla Blog.
Your Android tabs just got a lot more organized with Firefox
Tabs pile up fast on mobile. Imagine you’re planning a summer barbecue, and you start by searching for the best rib recipe. Twenty minutes later, you’re 17 tabs deep: comparing marinades, debating side dishes, checking the weather, making a grocery list and adding songs to a playlist.
None of those tabs are organized. They’re mixed in with everything else you’ve been browsing, making it hard to keep track of what you’re saving for later.
Now you can group related tabs in Firefox for Android, keeping them together in labeled, colored groups so you can actually find what you need when you need it.
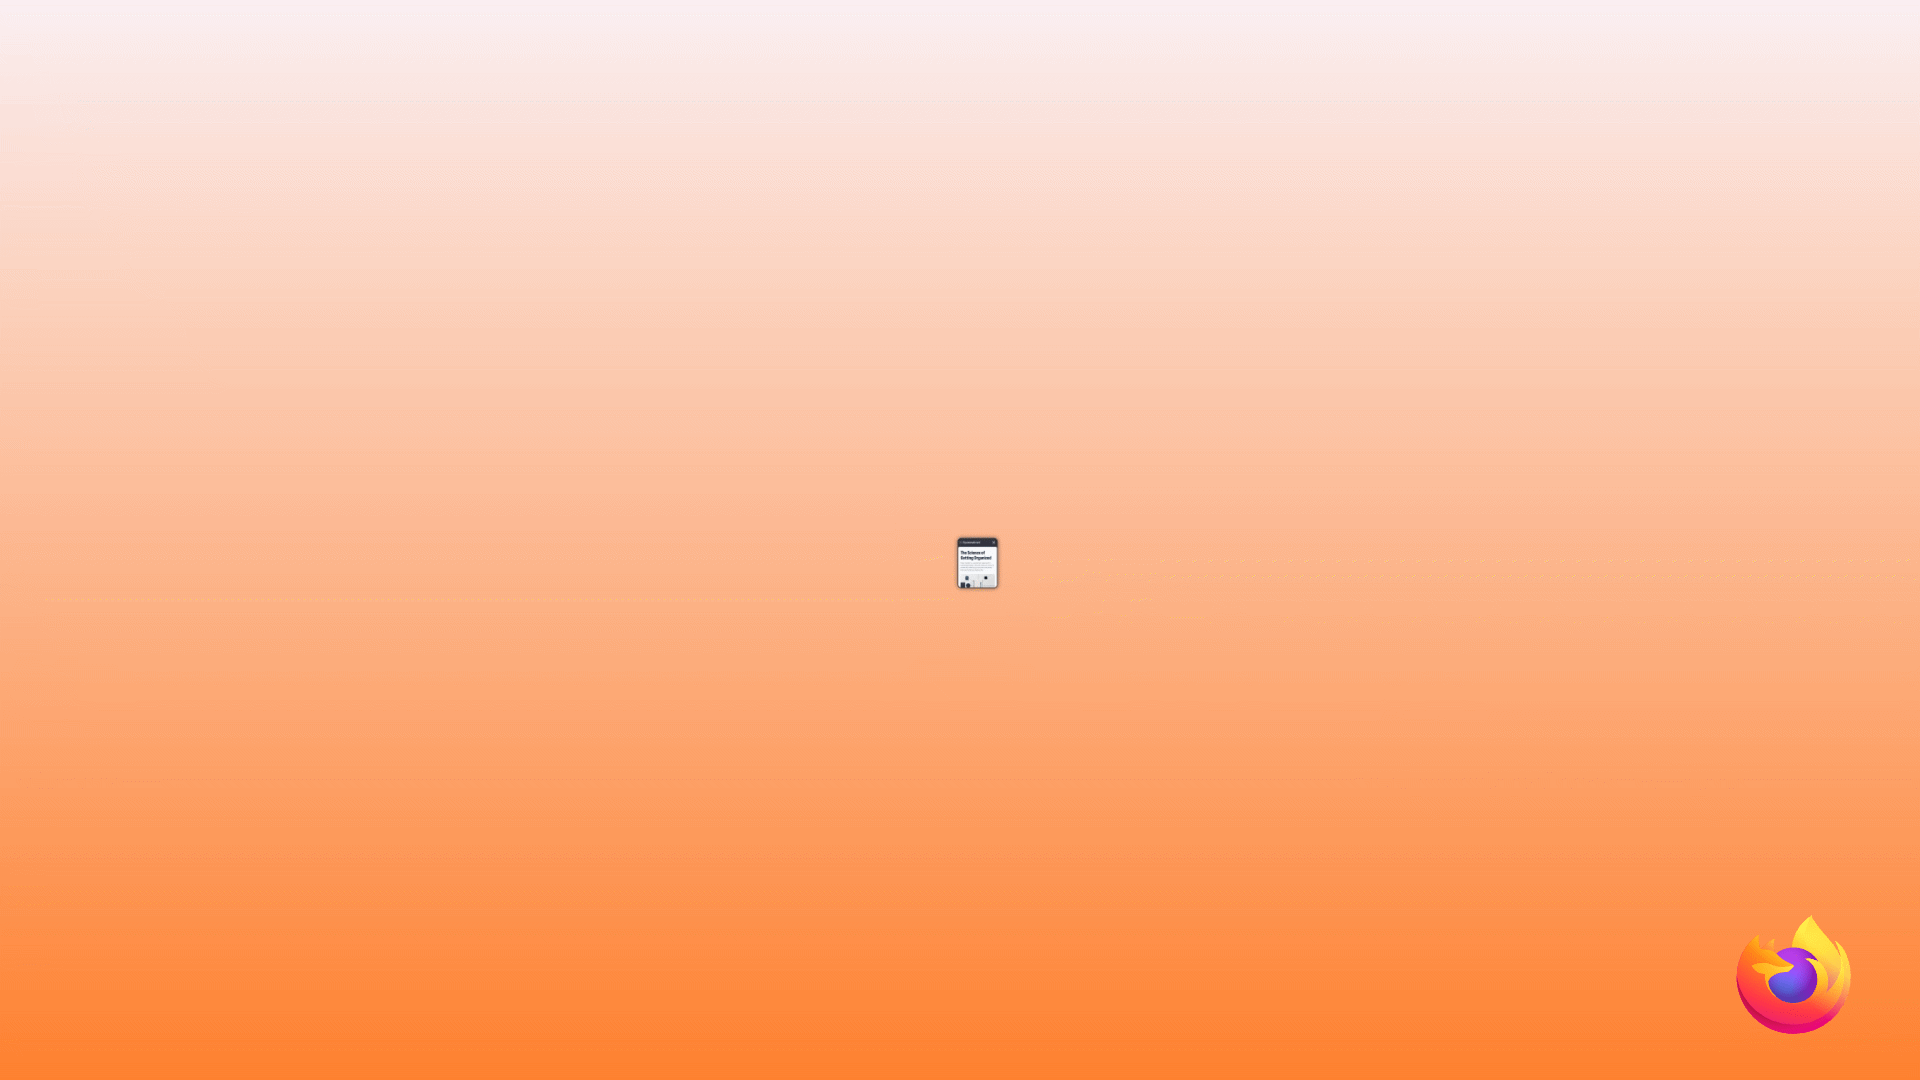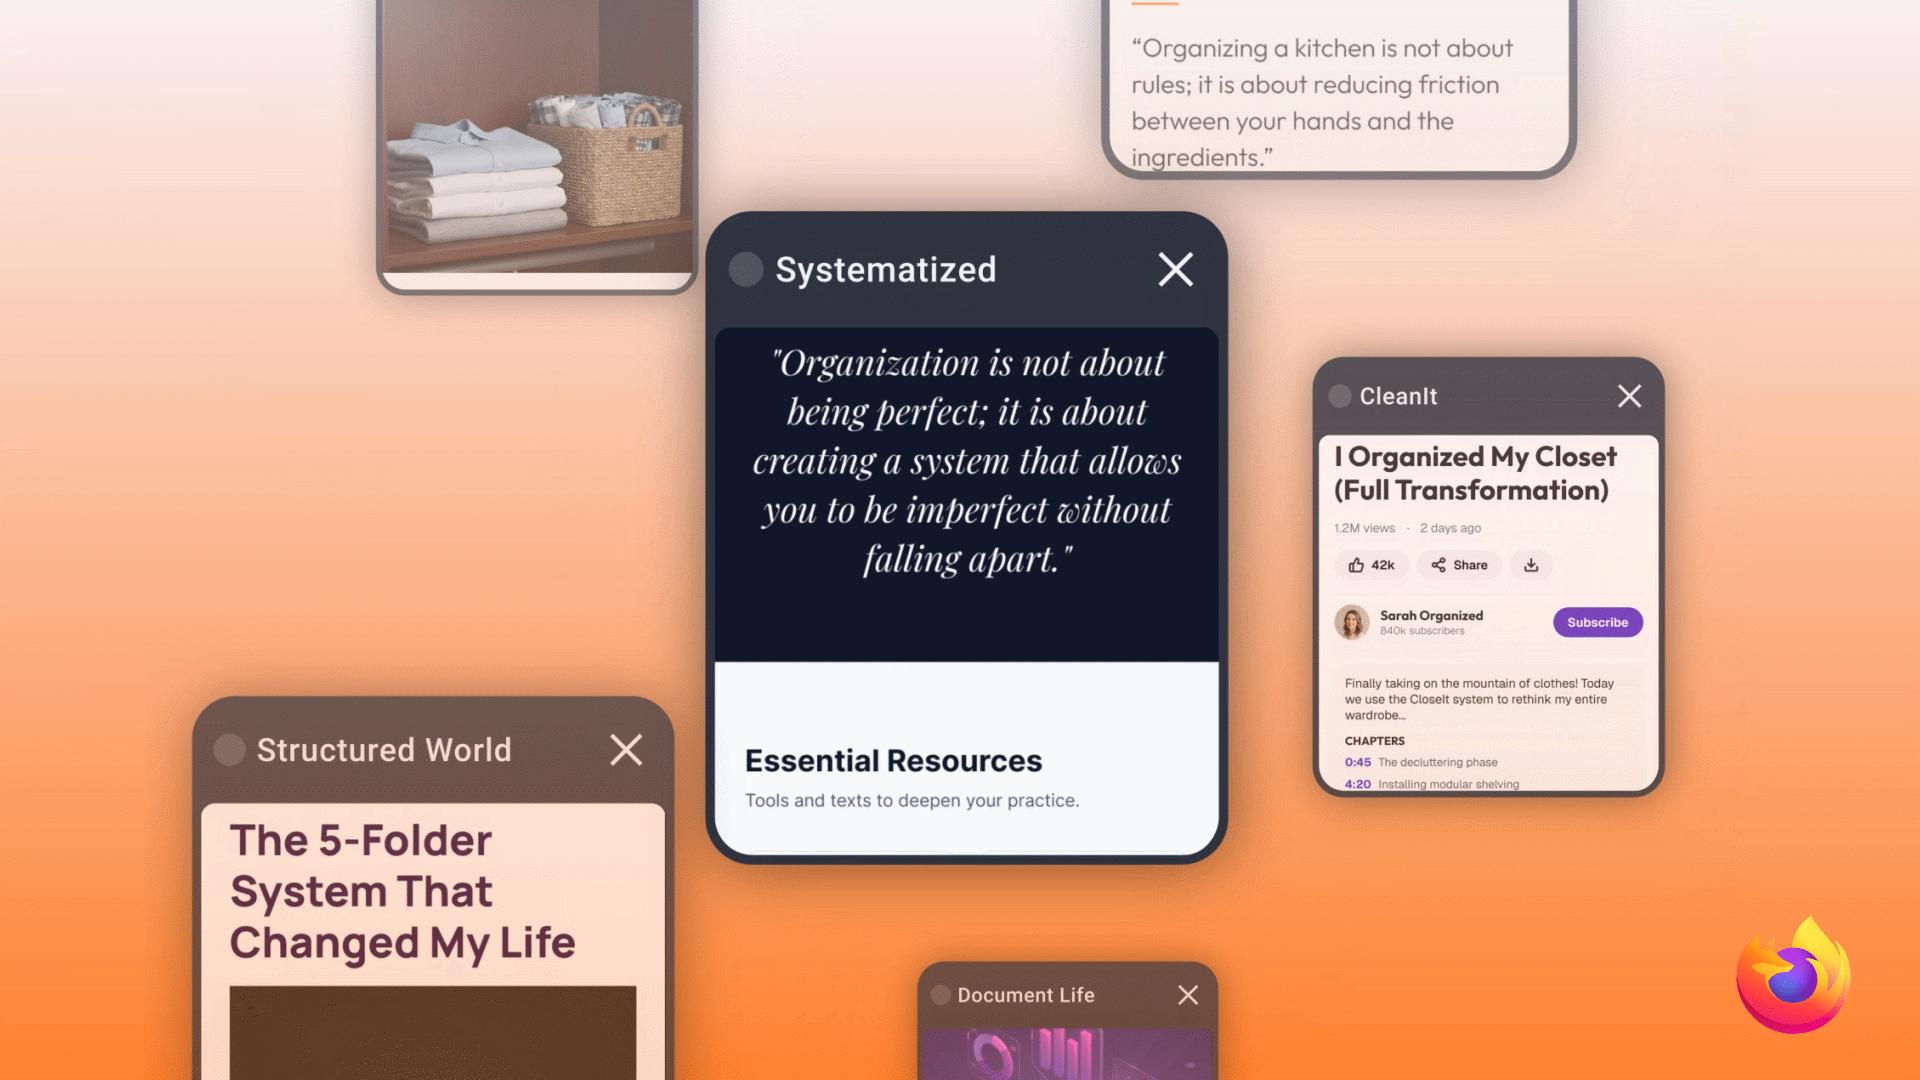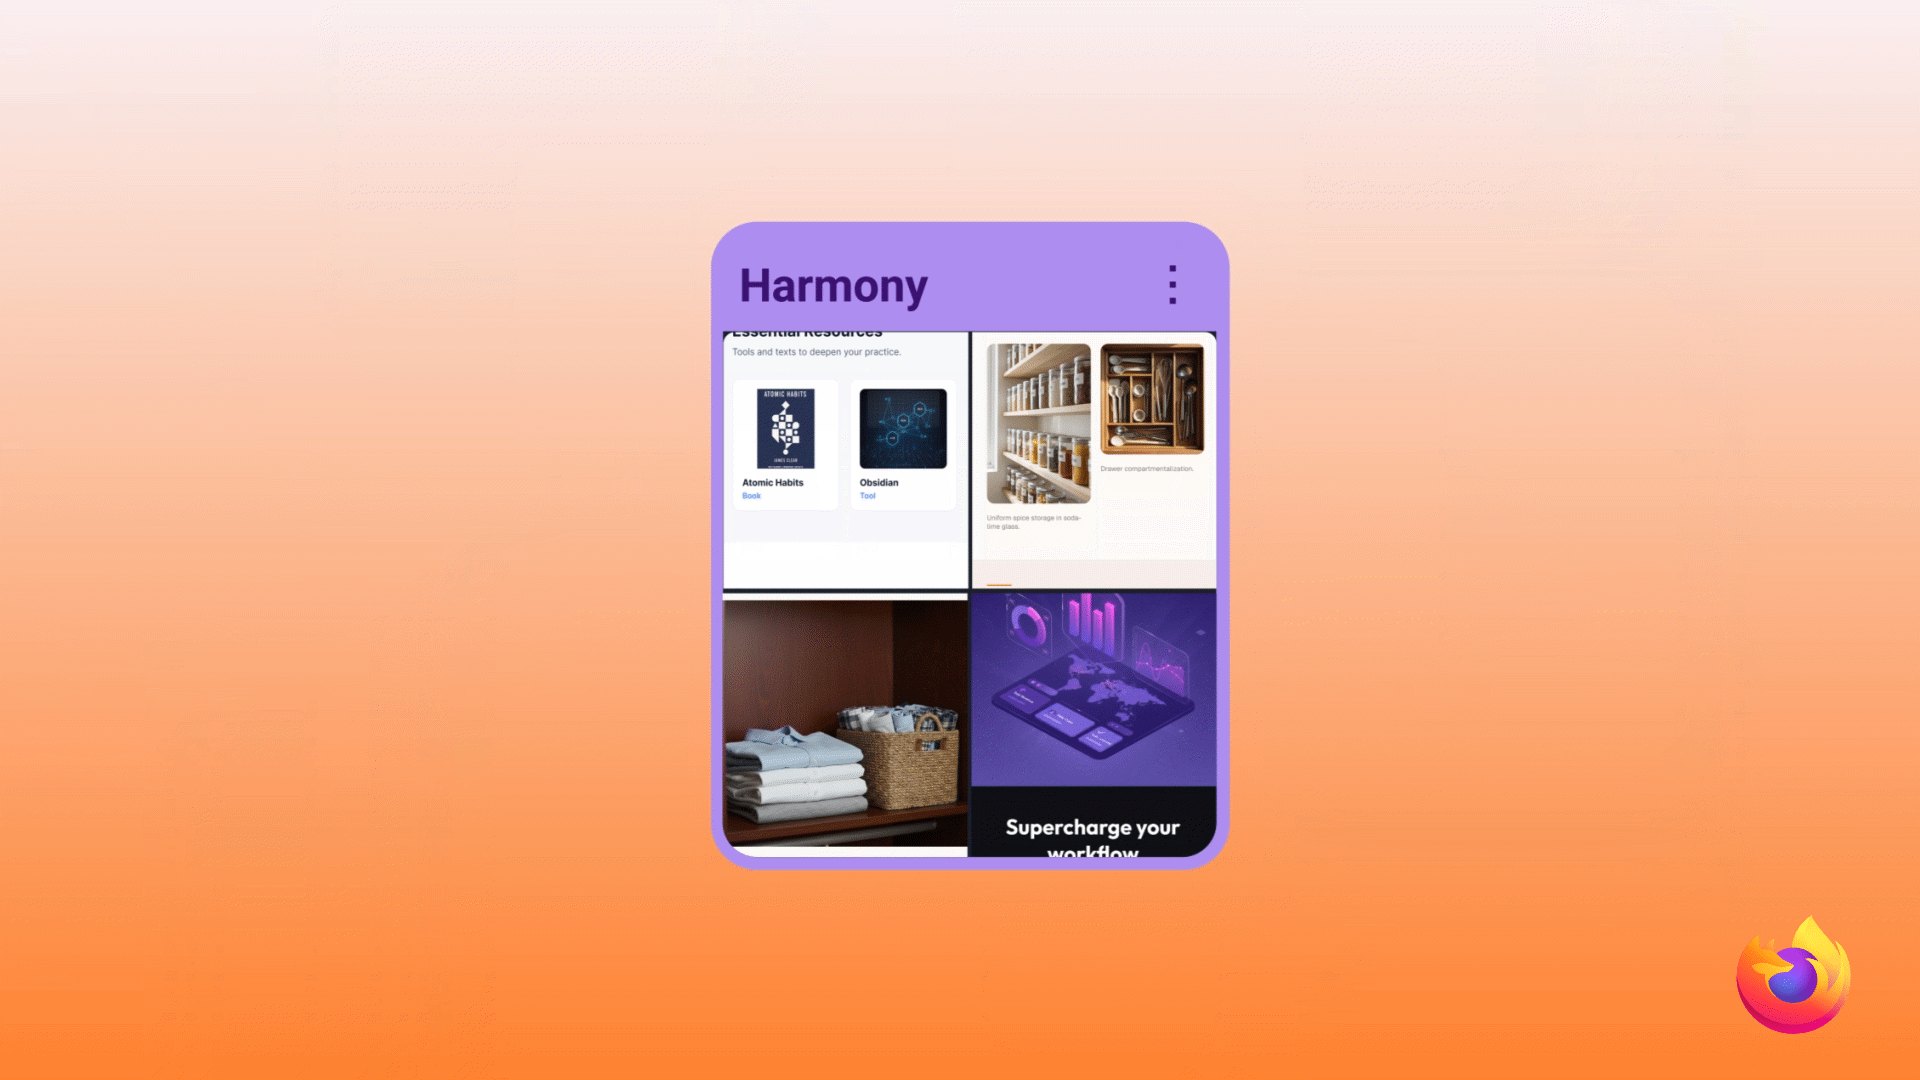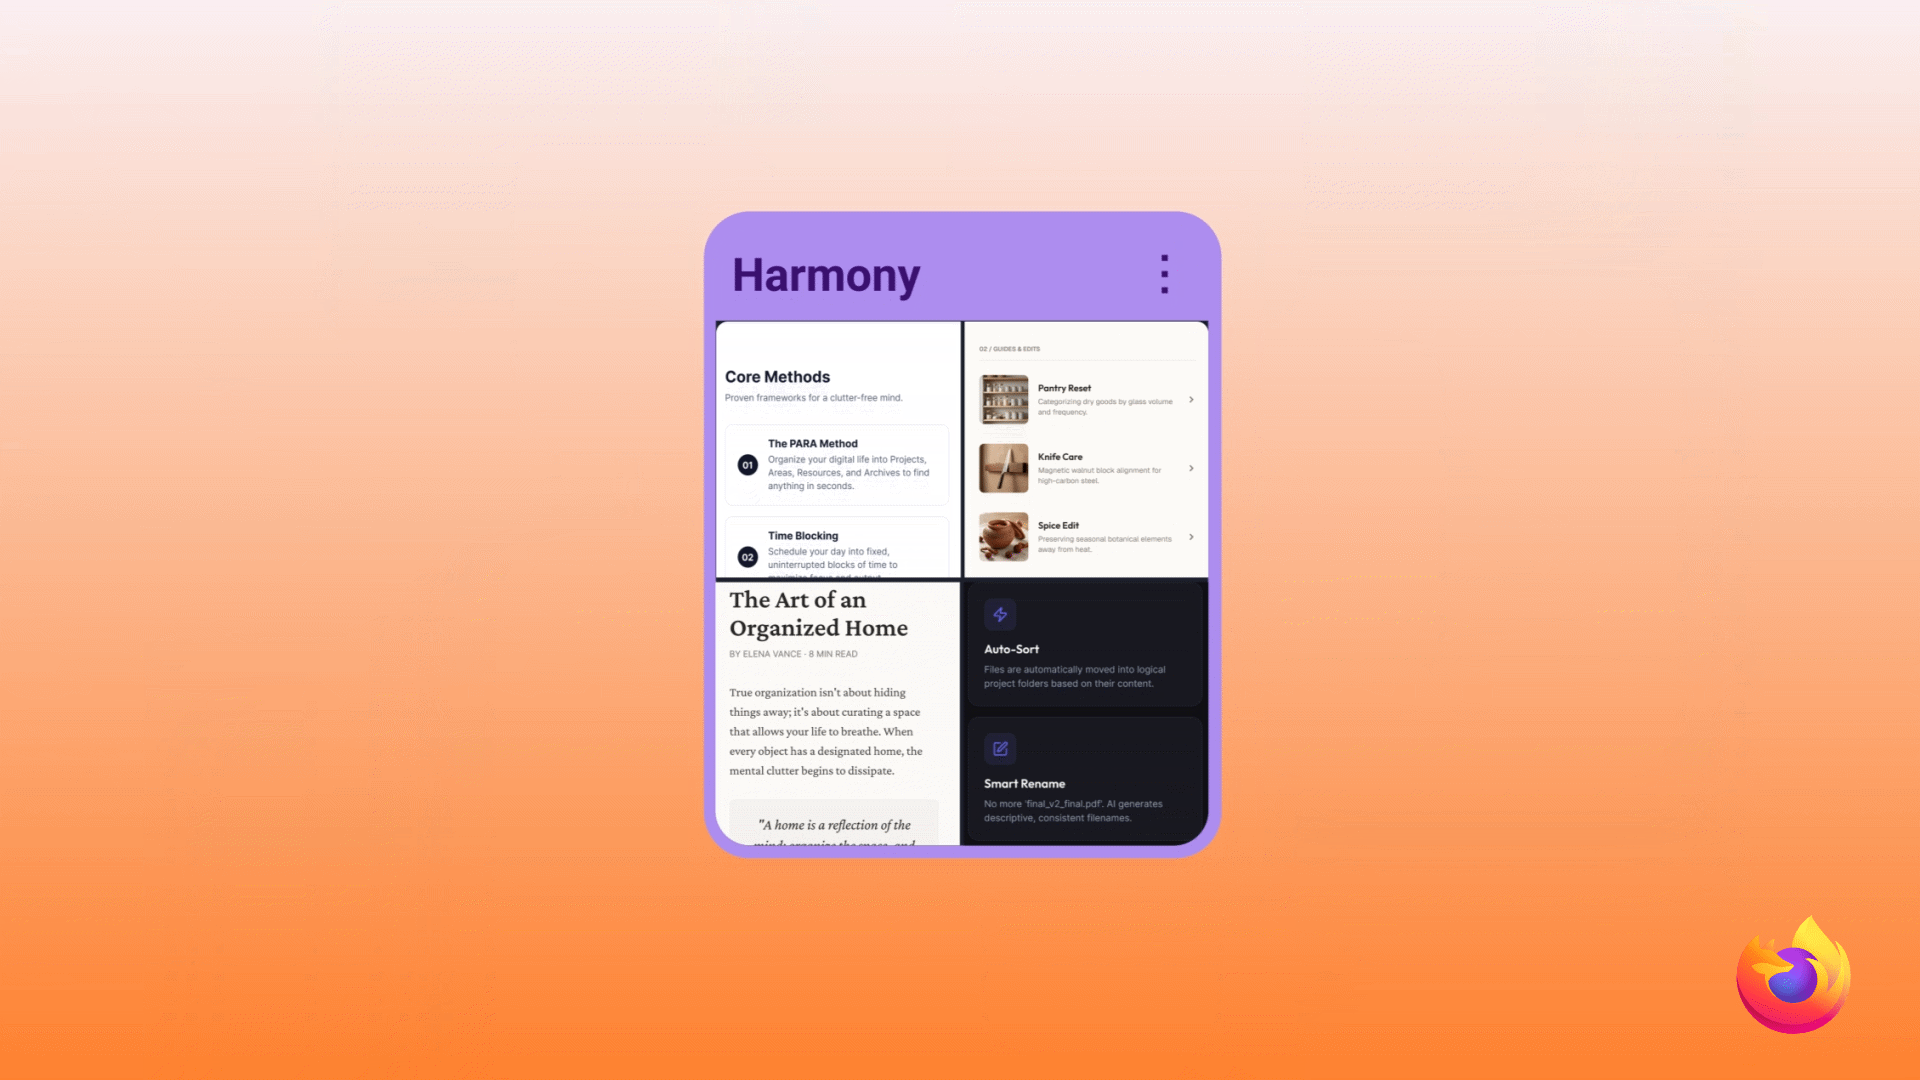 How it works
Drag one tab onto another, or select a few and tap “Add to group.” Name it, pick a color, and you’re done.
Each group appears as a single card in the tab tray rather than a dozen separate tabs. You can open it, rename it, recolor it, or delete it whenever you want. Search still finds tabs inside a group, too.
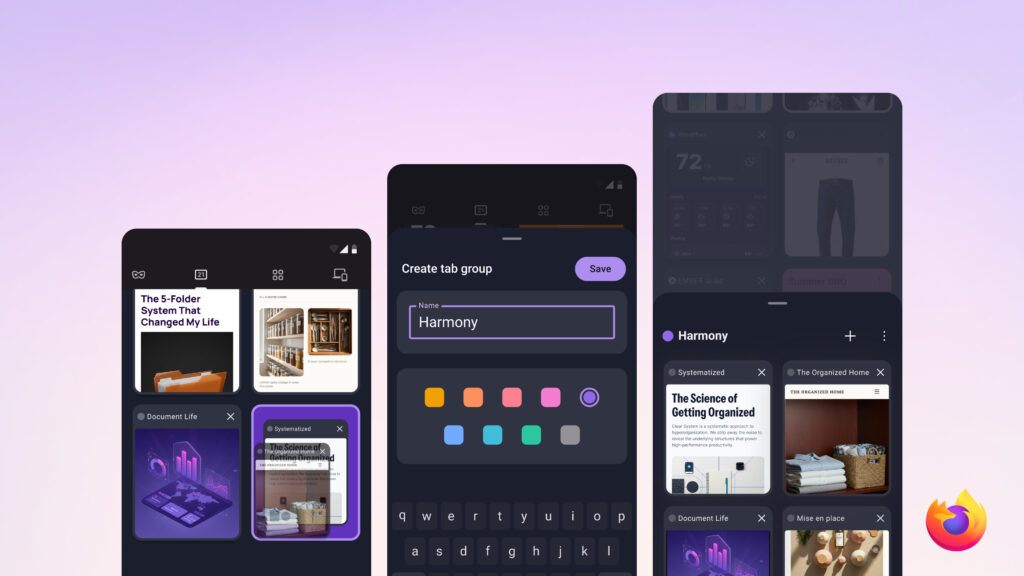
So when you’re standing in the produce aisle looking for that rib recipe, you won’t have to scroll past dozens of unrelated tabs just to find it. Everything for your barbecue is organized together in one place, ready when you need it.
Finally sorted, as it should beTab grouping was the most requested feature from Firefox mobile users in 2025. And we get it: your tabs shouldn’t get harder to manage the more you use your browser. Download the latest version of Firefox for Android now to try Tab Groups, with iOS support on the way.
The post Your Android tabs just got a lot more organized with Firefox appeared first on The Mozilla Blog.
Quick Answers: For the questions in between
You’re planning a trip. Reading an article. Following a recipe.
Then a question pops into your head. Sometimes it leads down a rabbit hole – with more searches, more tabs and plenty to explore. Other times, you just need a little context so you can get back to what you were doing.
That’s why we’re introducing Quick Answers for Firefox on iOS.
With Quick Answers, you can ask a question using your voice and get a concise answer. Just open a new tab, long-press the voice button and ask.
For example:
- “What does mellifluous mean?”
- “What is 95 degrees Fahrenheit in Celsius?”
- “What’s the difference between suede and nubuck?”
If a quick answer is all you need, you’re done.
If you want to dig in deeper, the links to supporting sources are there for exploration.
Built with transparency and privacy in mindWe’ve built Quick Answers to be transparent about how it works and what data is shared.
Voice is processed on your device using Apple’s speech recognition technology. No raw audio is stored or sent to the server, and Firefox doesn’t share your browsing history or personal context with the AI model. Only the transcribed text of your question is sent to generate an answer. You can turn the feature off at any time in Settings → AI Controls.
Quick Answers is starting to roll out today to Firefox for iOS users in the U.S. using English.
Oh, and if you’re wondering…
- Mellifluous means pleasant and musical to hear.
- 95 degrees Fahrenheit is 35 degrees Celsius.
- Suede is made from the underside of the hide, while nubuck is made from the outer side and buffed to create a soft, velvety texture.
 Take control of your internet Download Firefox
The post Quick Answers: For the questions in between appeared first on The Mozilla Blog.
Experience Better Browsing: Introducing Native Containers in Firefox 153
Today, we’re excited to announce the Preview of Containers in Firefox version 153, which lets you keep separate parts of your online life (work, shopping, personal, banking) logged into different accounts in the same browser window, but keeps your cookies and ad tracking isolated inside each container.
This means that stuff you do in one container isn’t seen by other containers. No longer will you search for a new hat to wear to a party, only to be inundated with ads for hats at every twist and turn on the internet for weeks to come.
For almost a decade, many of you have relied on our Multi-Account Containers extension to keep work, personal, and privacy-sensitive browsing separate without needing multiple browsers or profiles.
We’ve heard your feedback and understood the value you find in that separation. Now, we’re bringing the power of the Multi-Account Containers extension directly into the heart of Firefox for all to benefit from.
Why bring Containers into Firefox?Whether you’re managing multiple social media accounts, separating work projects from personal shopping, or simply keeping your banking activity distinct, Containers are designed to help you organize your digital space. By making Containers a native, first-party feature in Firefox 153, we are:
- Making it visible by default: You no longer need to hunt for an add-on to get started. Containers are built right into your browser, ready to help you manage your context from day one.
- Simplifying your workflow: We’ve focused on making it easier to open, create, and manage your containers from the places you already browse.
- Preserving what you love: For our long-time users who have relied on the add-on, the native experience is designed to maintain the core functionality, flexibility, and visual identity you depend on.
- Driving continued investment into the future of this feature, ensuring it lives on as a first party citizen of Firefox.
In this preview release, you can:
- Open tabs in specific containers: Keep your browsing activity isolated by context.
- Customize your workspace: Create and manage containers with your own names, colors, and icons.
- Manage settings easily: Control your container setup directly from the Firefox settings surface.
- Get Started: Right-click any tab or long-press the new tab (+) button to open a container tab — or head to Firefox Settings to create your first container.
If you’re already using the Multi-Account Containers, there’s nothing special you need to do. Not all of the features of the add-on are available in the first-party version of containers just yet, we’re still building them out. You can continue to use the add-on alongside the built in containers, no need to uninstall the add-on.
This release represents our first step in making Firefox more adaptable to how you actually live and work online. While this is just the beginning, we have plans to refine this experience and build a foundation for future features that make context separation even more seamless.
Join the Conversation
We’re eager to hear how this native experience fits into your daily routine. As you explore the new Containers Preview in Firefox 153, please let us know what you think by posting your feedback in this Mozilla Connect thread. Your feedback helps us shape the future of these tools and ensures we’re building features that truly matter to you.
Take control of your internet Download Firefox
The post Experience Better Browsing: Introducing Native Containers in Firefox 153 appeared first on The Mozilla Blog.
Over The Edge 2.0: what independent researchers found about browser choice on Windows
Two years ago Mozilla asked two leading experts on deceptive design, Dr. Harry Brignull and Cennydd Bowles, to look at how Microsoft was treating people who tried to use a different browser on Windows. Their report, Over The Edge, documented a pattern of design choices in Windows, Edge, and Bing that nudged, pressured, and at times tricked people into using Edge.
This morning, the same researchers are publishing Over The Edge 2.0. They retested the same questions across Windows 10 and Windows 11, and added two new dimensions. First, how does Microsoft’s approach change from one jurisdiction to another? They assessed Microsoft’s tactics across four regions: the USA, India, the UK, and Germany, as a representative country in the European Economic Area. Second, they examined how AI features, specifically Copilot, are being used to shape the same outcomes the original report identified.
Their conclusion is short. Microsoft still does not allow users to download, set as the default, or keep using alternative browsers without harmful interference. The patterns are documented, and they meet established definitions of coercion, deception, and manipulation.
There is one bright spot. In Europe, where the Digital Markets Act applies, some harmful design tactics are gone. The Bing ‘All you need is right here’ panel and its trick wording. The nagging Windows 10 ‘You’re almost done setting up your PC’ journey. The Copilot data toggles that default to “On” in the US and India, by contrast default to “Off” in the EEA and the UK. Same Windows. Same Edge. Same Copilot. Different design choices, because the law required them.
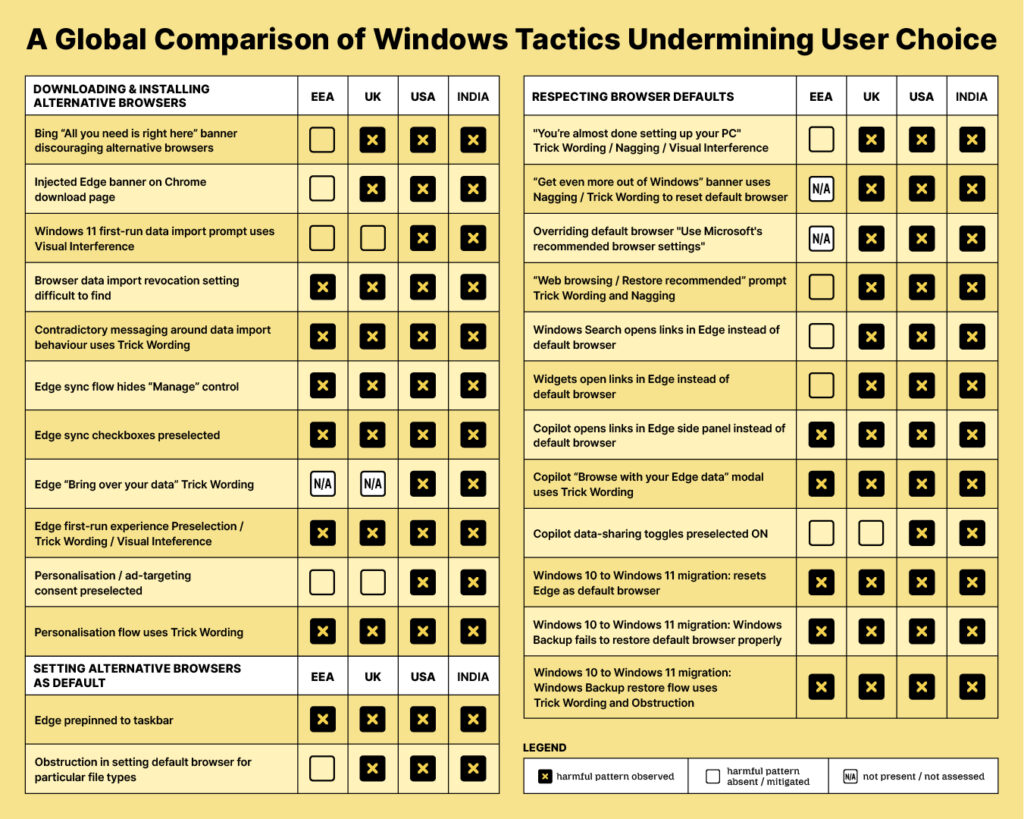
That is the heart of the report. Although the EEA product still has obvious harmful design patterns, Microsoft has built a fairer user experience for browser choice. It has shipped that experience to one region. Everywhere else, including the US, the UK, India, and Brazil, harmful design patterns continue. This is an active choice – and one that can be made differently.
The findings are the researchers’ own. Mozilla commissioned the work, and the report discloses that role, but the methodology, the screenshots, and the public journey database at edge.brignull.com let anyone check the evidence for themselves.
We make Firefox because we believe the web should serve people, not platforms. Firefox is independent, built by Mozilla, and designed around what is best for users, not what increases lock-in.
Read the full report here.
The post Over The Edge 2.0: what independent researchers found about browser choice on Windows appeared first on The Mozilla Blog.
Mozilla’s Inaugural ‘State of Open Source AI’ Report Is Here
Open source AI has crossed a threshold. For years the debate has centered around whether open models could ever compete with closed ones. This is no longer a debate we should be having. Today Mozilla is publishing its inaugural State of Open Source AI report, built on new analysis and a global survey of 950+ developers, showing that open models are no longer playing catch-up. The performance gap with top proprietary systems like ChatGPT and Claude has narrowed to just 3%, while costs have fallen up to 50x in three years.
But the report also surfaces a harder truth. Open models now power roughly a third of real-world AI usage, but capture only 4% of the revenue. So while the value is there, it just isn’t flowing back into the open ecosystem that made it possible. Meanwhile, the geopolitical picture is shifting fast.
Asia is racing aheadChina and East Asia now lead the world in open source AI adoption, at 89%, far ahead of the West, treating open source as a cornerstone of national strategy. Governments elsewhere are responding, with 12 new national AI strategies launched last year, and 47 countries now restrict foreign processing for critical workloads. The EU, Canada, and India are backing open ecosystems with real public investment, treating AI infrastructure as a strategic asset.
Developers want open models, but they can’t always ship them.For developers, the appetite for open source is there, and cost and privacy rank as developers’ top reasons for choosing models. But wanting to use open models and running them in production are different things. 79% of developers use open models, yet only 51% have deployed them in production, versus 63% for closed models.
As Álvaro Ruiz Cubero of SlashData, which fielded the survey for Mozilla, put it: “this gap indicates that there is not an issue purely of model quality, but of missing infrastructure. Deployment rates for open models barely increase with company size, highlighting a lack of mature tooling and support. At the same time, buyers are prioritising licensing terms (31%) and ownership (26%), signalling a clear shift toward control and flexibility over raw capability.”
The real battle has moved beyond the modelPerhaps the most important finding may be the least obvious. The layer that matters most isn’t the model. It’s the agentic harness: the software between people and models that decides what an AI system can see, remember, and do. Changing the surrounding software can affect performance more than switching the model itself. Whoever controls that layer controls how AI behaves in the world.
Right now, that layer is being built with very few guardrails. Users approve AI agent requests by default up to 93% of the time, with so-called “consent fatigue” going largely unnoticed.
“Open source AI has reached a turning point,” said Raffi Krikorian, Mozilla’s Chief Technology Officer. “It’s no longer about expanding access to models; it’s about who has the power to shape, audit, and improve them. Without investment in the infrastructure, tooling, and governance around open models, we risk locking in a system where only restrictive, closed AI can scale – and that doesn’t serve the public interest, or sovereignty over tech policy decisions.”
Be owners, not rentersOpen models offer what a subscription never can: owning your infrastructure instead of renting someone else’s. Companies like Microsoft and Uber are already rethinking their reliance on paid, closed AI tools as the bills add up. The economics are shifting and so is the thinking.
If you’re a CTO, a policymaker, a developer or an investor, this is the report for you. Read it, share it, and help build the infrastructure to make openness usable, not just possible.
Read the full Mozilla State of Open Source AI report here.
The post Mozilla’s Inaugural ‘State of Open Source AI’ Report Is Here appeared first on The Mozilla Blog.
Wrexham AFC and Firefox announce a multi-year, front-of-kit partnership
We don’t put our name on much. So when we do, it means something.
Starting with the 2026/27 season, Firefox is Wrexham AFC’s Official Web Browser Partner and front-of-kit sponsor on the men’s and women’s teams.
More than 160 years old and nearly lost for good, the football club was saved by the community that loved it and has been climbing ever since. Wrexham AFC built something real by doing things their own way and staying close to the community that carries them.
That’s a story we recognize. Firefox has spent more than 20 years as the browser people choose — not the one they’re handed. Backed by a nonprofit, we’ve never had to answer to shareholders, just to the people who use us. Two challengers, never the default, both here because our communities showed up for us.
Our partnership debuts this weekend on the new away kit, when Wrexham travels to Kraków for their opening pre-season fixture. And this is just the start: Expect content, product integrations and fan moments all season long.
“Both Wrexham AFC and Firefox are challenger brands that built passionate global communities by doing things differently and staying true to who they are,” Mozilla CMO John Solomon said. “Firefox has approached the internet with that same philosophy — building it as it should be, with people at the center.”
“We are thrilled to welcome Firefox as our new front-of-kit partner,” said Rob Mac and Ryan Reynolds, co-chairmen of Wrexham AFC. “We love an underdog story and both Wrexham and Firefox know the feeling of having to battle giants. It takes inventiveness, relentlessness and a pristine browsing history. So let’s effing go…”
Football needs Wrexham. The internet needs Firefox.
For more information on our partnership and upcoming 2026/27 season, follow @wrexham_afc on social media. Click here to download the independent browser that puts you first.
About Mozilla and Firefox
Mozilla is a global nonprofit backed technology organization that builds products, invests in startups, and advances policy to keep the internet open, fair, and worthy of trust. Firefox is the independent browser from Mozilla, known for strong tracking protection, open source code, and a focus on user choice, privacy and security.
About Wrexham AFC
Wrexham Association Football Club is based in Wrexham, North Wales, and after an historic, record-breaking three consecutive promotions are competing in the EFL Championship, the second tier of the English football league pyramid. Formed in 1864, they are the oldest Club in Wales and the third oldest professional team in the world. Wrexham have won the Welsh Cup a record 23 times and beaten some of the biggest clubs in the game in the English FA Cup and UEFA European Cup Winners Cup. The Racecourse Ground, home to Wrexham AFC, is the world’s oldest international stadium that continues to host international games.
Wrexham AFC is owned by Rob Mac and Ryan Reynolds. The goal of the owners is to grow the team and establish Wrexham AFC as a Premier League club in front of increased attendances, and in an improved stadium, while making a positive difference to the wider community in Wrexham. For more information, please visit wrexhamafc.co.uk or follow @wrexham_afc.
Take control of your internet Download Firefox
The post Wrexham AFC and Firefox announce a multi-year, front-of-kit partnership appeared first on The Mozilla Blog.
The web is evolving. So are we.
Earlier this month, we officially stood up Mozilla.org: a new 501(c)(3) nonprofit created to steward the long term success of the Mozilla Project.
Over the last year or so, I’ve said a lot about how AI is reshaping the web — and how we need to simultaneously stand up for the open internet Mozilla helped build and shape what the internet is becoming in the AI era. This is a huge and urgent challenge.
Mozilla has evolved and grown a great deal in order to step up to this challenge.
We are still a high impact philanthropic foundation and a browser company focused on user choice. But we are also: an email company built around privacy; an open source AI startup focused on developers; a place for people to create and share data on their own terms; and an investor in responsible tech startups.
These are all pieces of Mozilla today, and are all important levers as we try to shape where the internet is headed for the better.
We have created Mozilla.org to pull all of the different pieces of Mozilla together. It will act like a strategic endowment — allocating funding, managing our brands and shaping long term strategy — to ensure every part of Mozilla is well set up to advance the vision outlined in the Mozilla Manifesto. And, if we’re successful, it will help all of the pieces of Mozilla add up to more than the sum of their parts.
This is an important milestone for Mozilla. The challenge of fusing the values of the Mozilla Manifesto into this next era of the internet is huge. This updated structure will make it easier to nimbly direct our resources and orchestrate our actions to step up to this challenge.
At the same time, what we love about Mozilla stays the same. All of Mozilla’s organizations remain under the umbrella of the 501(c)(3) Mozilla Foundation, with the new non-profit operating the Mozilla portfolio of organizations on its behalf. Our mission — and our commitment to nonprofit ownership at the top — remain steadfast.
For more information on the new Mozilla.org non profit including an FAQ, see wiki.mozilla.org/mozilla_org
The post The web is evolving. So are we. appeared first on The Mozilla Blog.
Thunderbird Blog: Thunderbird Monthly Development Digest – June 2025
Hello once more from the Thunderbird development team! For many of our team members, the summer has started with our annual sprint to release ESR and enjoy a little time afk, as our colleagues in the southern hemisphere hunker down for winter and power through a pile of work down under.
Extended Support Release is alive!For enterprise users (and those who have been using Thunderbird for a long time and found themselves on the Extended Support Release channel), the annual release “ESR 140 Eclipse” has made it to our update servers and will be pushed out over the next few weeks.
We had initially planned to release within hours or days of the Firefox ESR release, but much of the ESR build process has changed in the last 12 months (largely due to the Firefox mozilla-central Git migration) – so we ended up learning a lot and took pause to release at a time that produced the best experience for the majority of our users.
In the hours following the initial release, we have another build hot on its heels which includes some important patches and will ship today or tomorrow. Things move fast around here!
If waiting a year doesn’t sound appealing to you, our Monthly release may be better suited. It offers access to the latest features, improvements, and fixes as soon as they’re ready. Watch out for an in-app invitation to upgrade or install over ESR to retain your profile settings.
Exchange support in DailyThe EWS 0.2 milestone has been completed and the feature was turned on by default in Daily release to facilitate more manual QA testing. In order to provide test coverage on a variety of EWS server versions and configurations, we’re tackling in a few ways:
- Adding a small number of Hosted Exchange 2016 mailboxes to facilitate testing of all existing functionality at endpoints other than O365.
- Contacting enterprise partners who can help us test on their infrastructure – please get in touch if this might be you!
- Hosting our own EWS instance that allows us to configure a variety of security and authentication settings to ensure our code works for all
- Focusing on automated test coverage throughout the month of July
Since my last update, the team has grown even more and made great progress on items in our “Phase 2 operations” and “Phase 2 polish” milestones, with these features delivered recently:
- EWS-to-EWS move & copy for items and folders
- Authentication Error handling
- Server Version handling
- Threading support
- Folder updates & deletions during sync operations
- Folder cache cleanup
- Folder copy/move
- Bug fixes!
We plan to temporarily expand the team during July to include two more of our most experienced senior engineers to push this project over the finish line and tackle some remaining complexities:
- Automated test coverage
- Message filtering
- Setting as Junk/Not Junk
- Bug backlog
Keep track of feature delivery here.
Account HubThe new email account feature was enabled as the default experience for users adding their second email account. It is now available in all release channels. We’re currently finalizing the UX and associated functionality that detects whether account autodiscovery requires a password, and reacts accordingly – which will hopefully be uplifted once stable.
We’re wrapping up the redesigned Account Hub UI for Address Book account additions this week, which we’ll enable for users on Daily and beta in the coming weeks. Look out for it in our Monthly release 142.
Global Message DatabaseSince the last update, we’ve landed a landslide of patches. Critical refactoring continues to clean and optimize the code, in many cases clearing the way for new beneficial protocol implementations.
To follow their progress, take a look at the meta bug dependency tree. The team also maintains documentation in Sourcedocs which are visible here.
Recent Features and FixesA number of other features and fixes have reached our Daily users this month. We want to give special thanks to the contributors who made the following possible…
- Even more improvements to notifications!
- Many, many port bugs to adapt Thunderbird to upstream changes
- Fix spell check and other windows impacted by Firefox code updates
- and many more listed in release notes for beta.
If you would like to see new features as they land, and help us squash some early bugs, you can try running daily and check the pushlog to see what has recently landed. This assistance is immensely helpful for catching problems early.
—Toby Pilling
Senior Manager, Desktop Engineering
The post Thunderbird Monthly Development Digest – June 2025 appeared first on The Thunderbird Blog.
Robert Kaiser: Integrating Magento 2 Shop With FreeFinance and Custom Merchandise Management
To manage our products, which we get from different vendors (sometimes the same product via different vendors) as well as plan and manage our orders, I built an internal, custom merchandise management in my own PHP framework or CMS CBSM (which is also used for this blog, for example). I did this mostly out of convenience as I have and maintain this system anyhow and I needed some database tables with fitting UI for managing our merchandise, vendors, and more (even conventions we may want to run booths at).
OTOH, the public shop is (as you may notice when looking at the website) an installation of Magento 2 (i.e. the open-source version of what is nowadays called "Adobe Commerce"). We decided to run that system because we are partnering closely with MCO Shop, which is a local ham radio and electronics shop, and they already had this software running previously on the servers we share and know how to work with it, run the upgrades, and maintain it. After all, when building a new business, as in so many areas of life, it always helps if you can share some resources and knowledge with others. First, I adapted the Magento theme to make it look more "space-like", mostly importantly, having a dark instead of light background. Once that worked well enough, I still had to get those products that we actually ordered from my custom management system into this Magento shop. Initially, I did this via creating a big CSV file and importing that into the shop, but it was clear that we needed a more fine-grained solution in the long run that can add and update entries individually.
Additionally, when we run booths on our "away missions" to events/conventions (or whenever we otherwise sell anything in person), Austrian law requires us to use a cash register system that follows strict rules and passes a certification so that the government can be sure we pay taxes for everything we sell. For that we decided to use a solution integrated into our bookkeeping system, which runs online as a web service as well, a specialized Austrian solution called FreeFinance. And of course, the cash register needs a full list of products and prices as well, which we also initially solved with a CSV creation and import in anticipation of a more fine-grained solution after our first big appearance at Austria Comic-Con in early June.
As icing on the cake, we also wanted to generate nicely styled invoice documents in FreeFinance for all online shop orders that weren't paid via the cash register, and in the future, we'll want to make the online shop automatically aware of merchandise sold at events so they are removed from available stock for online purchases.
To achieve that, I looked into the APIs that both Magento and FreeFinance provide, accessing them from the custom internal system that I have full access to and that is required for providing the merchandise data anyhow. I found that the FreeFinance API is relatively simple, well-documented and does authentication via OAuth2, which I already had some knowledge of (and code to access it) from other projects, including some code already in the CBSM system for facilitating its own logins. That said, Magento is a different beast: its product catalog feature set is way more complex, and so is its API. Also, there is no well-structured collective documentation that would explain what various things mean or what is preferably done in what way (often there are multiple paths to the same result), it's a lot of turning on developer mode so that a Swagger/OpenAPI UI is available on your installation and then trying around there and searching the web for what could work how and what value could mean what. In addition, authentication is done via OAuth1, which is more complicated than its successor, and which I didn't have any pre-existing code for, though I could build on some code from their tutorial. Also, as we're running Magento ourselves on the server side, I could more easily try around things than with FreeFinance, which is a hosted service and I needed to request access credentials from their team. But FreeFinance gave us access to a testing system, whereas for Magento, for various reasons, we only have a live system and no staging/testing environment, so we can't "play around" very much when testing.
I wrote quite a bit of code for all those cases, the simplest part was and is surely updating the cash register with our products, the only slight complication there is adding categories if needed. For adding products to the shop, I needed to respect all kinds of things, like creating and managing configurable products, adding values to some attributes, uploading images, managing categories, and more. And the curious structure of the Magento API, which requires way more detailed action than the CSV import route, did at times make this even more complicated - but it works now and I can just add or change a product in the merch management and at the latest on the next day, both the shop and the cash register have updated to those changes (I can trigger the sync jobs earlier if required). For creating the invoice documents, I could base some things on a make.com "blueprint" provided by FreeFinance, but for one thing, we don't want to use a paid third-party service if we can automate this ourselves, and for the other, we have some restrictions and specialties of our own there (like only generating invoices for orders actually paid via the web shop payment integration and not in person via the cash register). I did run into some curiosities there, like the Magento order API result containing several pieces of data multiple times, or us initially using a document layout template that didn't allow for different products having different VAT rates (which we require) - but that's working now as well. The reverse part about getting cash register purchases into the online shop is still on my plate, but I now have a good plan for how to do that, and some time until our next big "away mission" where this will be important to have.
All in all, this has been a quite interesting experience, and I'm sure now that I am comfortable with working with those systems and APIs, I will do more with them in the long run - and our Trade Post 47 hopefully will still grow as well and therefore have additional requirements in the future. If you are a developer and have questions about some details, feel free to contact me - and if you are running such systems yourself and need a developer who can adapt them in a similar fashion, I'm happy to offer those services as a contractor!
Andrew Sutherland: Andrew’s Searchfox Roadmap 2022
Searchfox (source, config source) is Mozilla’s primary code searching tool for Firefox introduced by Bill McCloskey in 2016 which built upon prior work on DXR. This roadmap post is the second of two posts attempting to lay out where my personal efforts to enhance searchfox are headed and the decision making framework that guides them. The first post was a more abstract product vision document and can be found here.
Discoverable, Extensible, Powerful QueriesSearchfox has a new “query” endpoint introduced in bug 1762817 which is intended to enable more powerful queries. Queries are parsed using :kats‘ query-parser crate which allows us to support our existing (secret) key:value syntax in a more rigorous way (and with automatic parse correction for the inevitable typos). In order to have a sane execution model, these key/value pairs are mapped through an extensible configuration file into a pipeline / graph execution model whose clap-based commands form the basis of our testing mechanism and can also be manually built and run from the command-line via searchfox-tool.
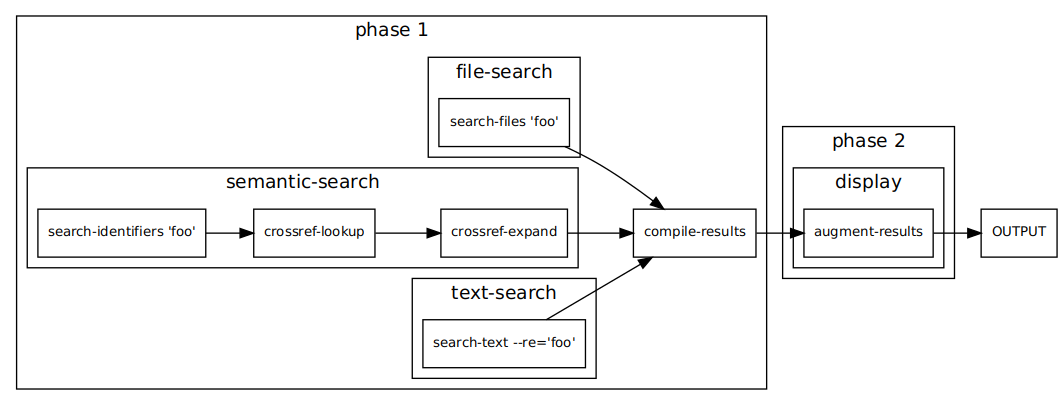
Above you will find a diagram rendering the execution pipeline of searching for foo manually created from the JSON insta crate check output for the query. Bug 1763005 will add automatically generated diagrams as well as further expanding on the existing capability to produce markdown explanations of what is happening in each stage of the pipeline and the values at each stage.
While a new query syntax isn’t exciting on its own, what is exciting is that this infrastructure makes it easier to add functionality with confidence (and tests!). Some particular details worth discussing:
Customizable, Shareable QueriesBug 1799796: Do you really wish that you could issue a query like webidl:CacheStorage to search just our WebIDL files for “CacheStorage”? Does your team have terminology that’s specific to your team and it would be great to have special search terms/aliases but it would feel wrong to use up all the cool short prefixes for your team? The new query mechanism has plans for these situations!
The new searchfox query endpoint looks like /mozilla-central/query/default. You’ll note that default looks like something that implies there are non-default options. And indeed, the plan is to allow files like this example “preset” dom.toml file to layer additional “terms” and “aliases” onto the base query_core.toml file as well as any other presets you want to build off of. You will need to add your preset to the mozsearch-mozilla repository for the tree in question, but the upside is that any query links you share will work for other people as well!
Faceting in Search Results with Shareable URLsBug 1799802: The basic idea of faceted search/filtering is:
- You start with a basic search query.
- Your results come back, potentially quite a lot of them. Too many, even!
- The faceting logic looks at the various attributes of the results and classifies or “facets” them. Does that sound too circular? We just throw things in bins. If a bin ends up having a lot of things in it and there’s some hierarchy to its contents, we recursively bin those contents.
- The UI presents these facets (bins), giving you a high level overview of the shape of your results, and letting you limit your results to only include certain attribute values, or to exclude based on others.
- The UI is able to react quickly because it already knows about the result set
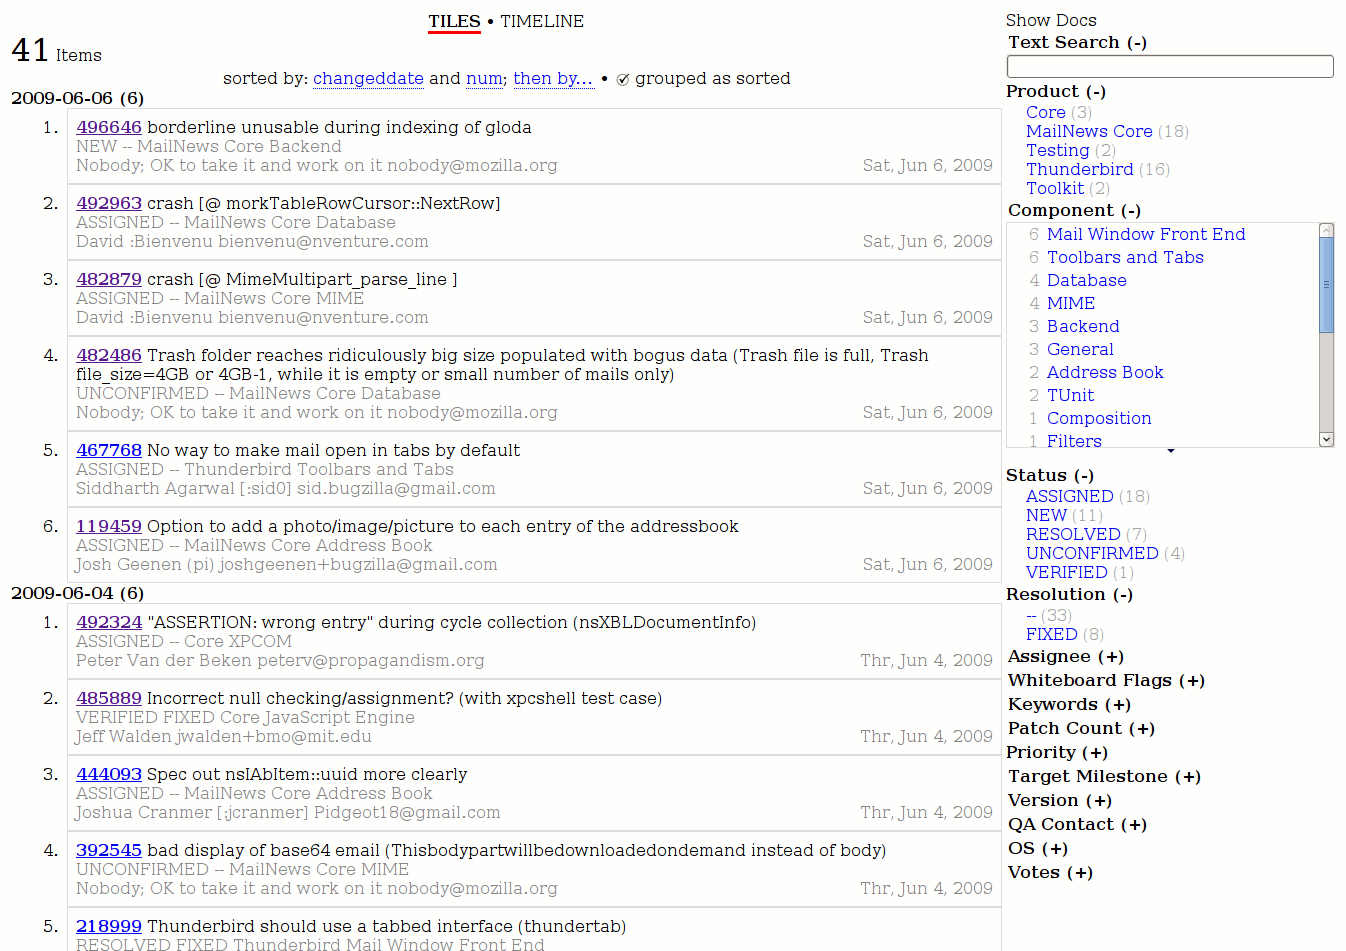
The cool screenshot above is of a SIMILE Exhibit-based faceting UI I created for bugzilla a while back which may help provide a more immediate concept of how faceting works. See my exhibit blog tag for more in the space.
Here are some example facets that search can soon support:
- Individual result paths: Categorize results by the path in which they happen. Do you not want to look at any results under devtools/? Push a button and filter out all those devtool results in an instant! Do you only care about layout/? Push a button and only see layout results!
- Subsystem facets: moz.build files labels every file in mozilla-central so that it has an associated Bugzilla Component. As of Bug 1783761 searchfox now also derives a subsystem mapping from the bugzilla components, which really just means that if you have a component that looks like “Core :: Storage: IndexedDB”, searchfox transforms that first colon into a slash so we get “Core/Storage/IndexedDB”. This would let you restrict your results to “Core/Storage” without having to manually select every Storage bugzilla component or path by hand.
- Symbol relationships: Did you search for a base class or virtual method which has a number of subclasses/overrides? Do you only care about some subset of the class hierarchy? Then restrict your results to whatever the portion of the set you care about.
- Recency of changes: Do you only care about seeing results whose blame history indicates it happened recently? Can do! Or maybe you only want to see code that hasn’t been touched in a long time? Uh, that might work less well until we improve the blame situation in Bug 1517978, but it’s always nice to have something to dream about.
- Code coverage: Only want to see results that runs a lot under our tests? Sure thing! Only want to see results that seem like we don’t have test coverage for? By looking at the result you’re now morally obligated to add test coverage!
Key to this enhancement is that the faceting state will be reflected in the URL (likely the hash) so that you can share it or navigate forward and back and the state will be the same. It’s all too common on the web for state like this to be local to the page, but key to my searchfox vision is that URLs are key. If you do a lot of faceting, the URL may become large an unwieldy, but continuing in the style of :arai‘s fantastic work on Bug 1769936 and follow-ups to make it easy to get usable markdown out of searchfox, we can help wrap your URL in markdown link syntax so that when you paste it somewhere markdown-aware, it looks nice.
Additional Query ConstraintsA bunch of those facets mentioned above sound like things that it would be neat to query on, right? Maybe even put them in a preset that you can share with others? Yes, we would add explicit query constraints for those as well, as well as to provide a way to convert faceted query results into a specific query that does not need to be faceted in Bug 1799805.
A variety of other additional queries become possible as well:
- Searching for lines of text that are near each other, or not near each other, or maybe both inside the same argument list.
- Locating member fields by type (Bug 1733217), like if you wanted to find all member fields that are smart or raw pointer references to nsILoadInfo.
- Bug 1779340: Function/method argument list magic.
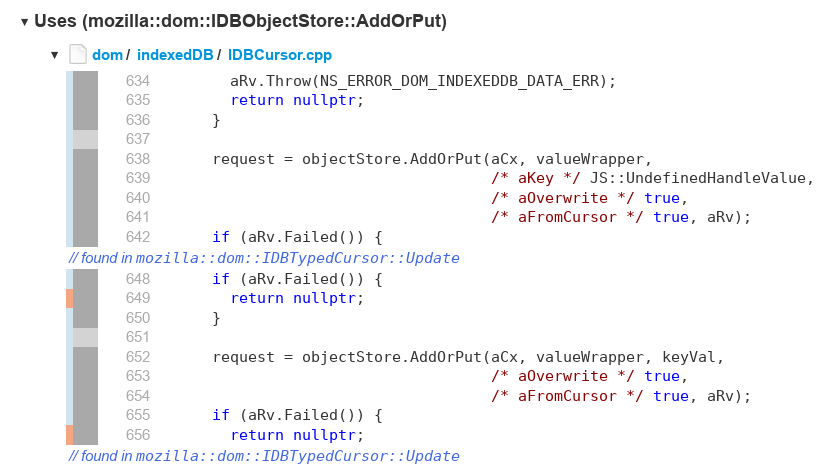 Current query results for C:4 AddOrPut
A major limitation for searchfox searches has been a lack of support for context lines. (Disclaimer: in Bug 1414954 I added secret support for fulltext-only queries by prefixing a search with context:4 or similar, but you would then want to force a fulltext query like context:4 text:my actual search or context:4 re:my.*regexp[y]?.*search.) The query mechanism already supports full context, as the above screenshot is taken from the query for C:4 AddOrPut but note that the UX needs more passes and the gathering mechanism currently needs optimization which I have a WIP for in Bug 1794177
Diagrams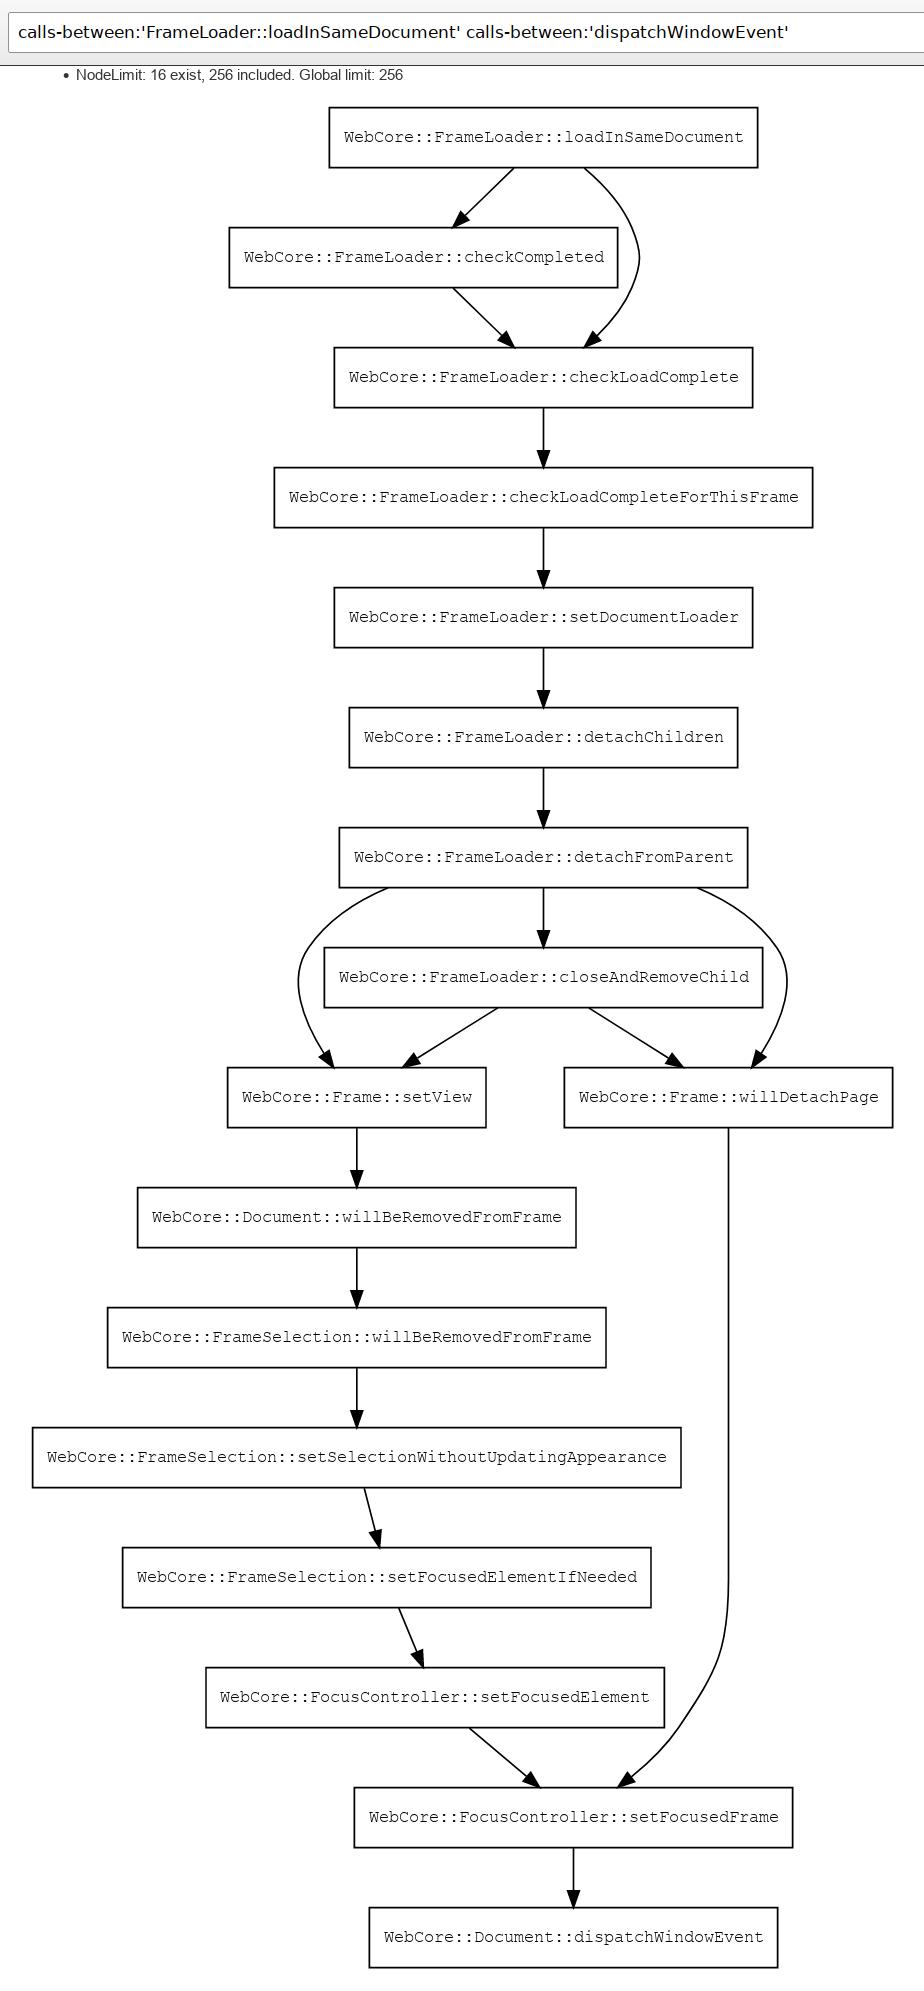
The above is a screenshot of a live diagram I just generated with the query calls-between:’WebCore::FrameLoader::loadInSameDocument’ calls-between:’WebCore::Document::dispatchWindowEvent’ against our searchfox index of webkit.
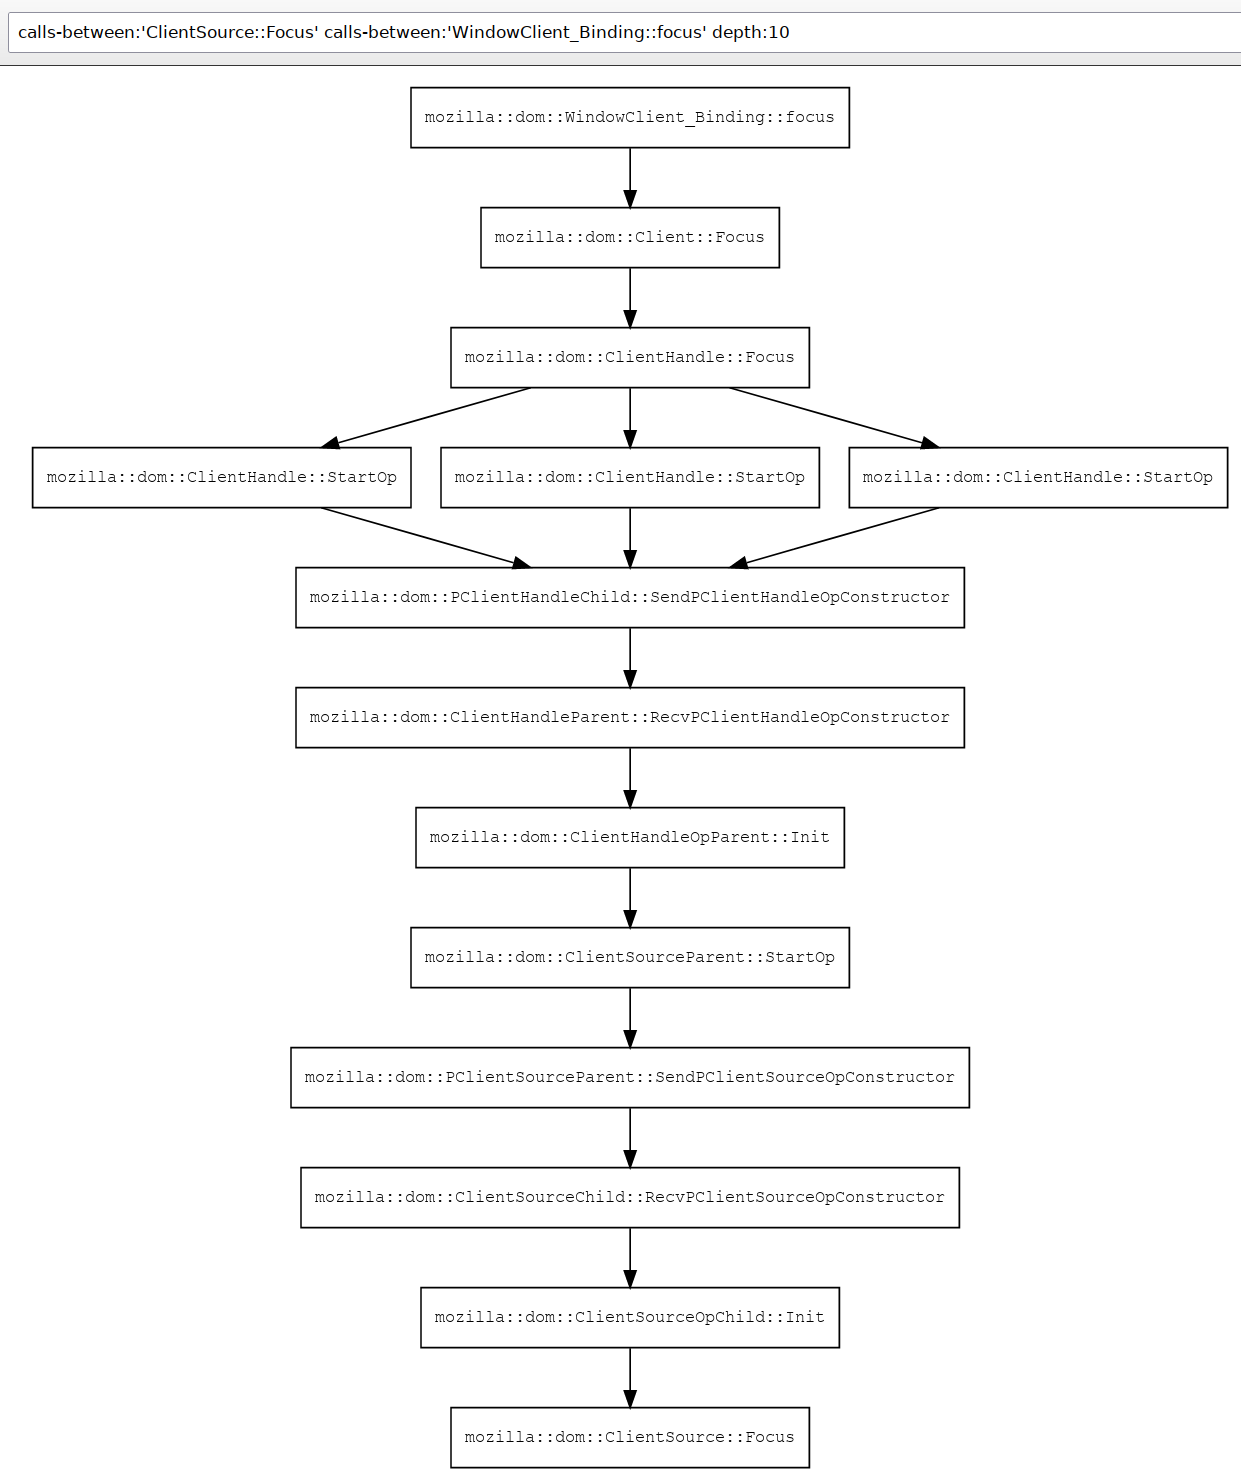
This next diagram is a screenshot of a live diagram from mozilla-central I just generated with the query calls-between:’mozilla::dom::ClientSource::Focus’ calls-between:’mozilla::dom::WindowClient_Binding::focus’ depth:12 and which demonstrates searchfox’s understanding of our IPDL bindings, as each of the SendP*/RecvP* pairs is capturing the IPC semantics that are only possible because of searchfox’s understanding of both C++ and IPDL.
The next steps in diagramming will happen in Bug 1773165 with a focus on making the graphs interactive and applying heuristics related to graph clustering based on work on the “fancy branch” prototype and my recent work to derive the sub-component mapping for files that can in turn be propagated to classes/methods so that we can automatically collapse edges that cross sub-component boundaries (but which can be interactively expanded). This has involved a bit of yak-shaving on Bug 1776522 and Bug 1783761 and others.
Note that we also support calls-to:'Identifier' in the query endpoint as well, but the graphs look a lot messier without the clustering heuristics, so I’m not including any in this post.
Most of my work on searchfox is motivated by my desire to use diagrams in system understanding, with much of the other work being necessary because to make useful diagrams, you need to have useful and deep models of the underlying data. I’ll try and write more about this in the future, but this is definitely a case where:
- A picture is worth a thousand words and iterations on the diagrams are more useful than the relevant prose.
- Providing screen-reader accessible versions of the underlying data is fundamental. I have not yet ported the tree-dual version of the diagram logic from the “fancy” branch and I think this is a precondition to an initial release that’s more than just a proof-of-sorta-works.
Our in-tree docs rendered at https://firefox-source-docs.mozilla.org/ are fantastic. Searchfox cannot replace human-authored documentation, but it can help you find them! Have you spent hours understanding code only to find that there was documentation that would help clarify what was going on only after the fact? Bug 1763532 will teach searchfox to index markdown so that documentation definitions and references show up in search and that we can potentially expose those in context menus. Subsequent steps could also index comment contents.
Bug 1458882 will teach searchfox how to link to the rendered documentation.
Improved Language Support New Language Support via SCIPWith the advent of LSIF and SCIP and in particular the work by the team at sourcegraph to add language indexing built on existing analysis tools, there is now a tremendous amount of low hanging fruit in terms of off-the-shelf language indexing that searchfox can potentially ingest. Thanks to Emilio‘s initial work in Bug 1761287 we know that it’s reasonably straightforward to ingest SCIP data from these indexers.
For each additional language we want to index, we expect the primary effort required will be to make the indexer available in a taskcluster task and appropriately configure it to index the potentially many component roots within the mozilla-central mono-repo. There will also be some searchfox-specific effort required to map the symbols into searchfox’s symbol namespace.
Specific languages we can support (better):
- Javascript / Typescript via scip-typescript (Bug 1740290): scip-typescript potentially allows us to expose the same enhanced understanding of JS code, especially module-based JS code, that you experience in VS code, including type inference/extraction from JSDoc. Additionally, in Bug 1775130 we can leverage the amazing eslint work already done to bring enhanced analysis to more confusing situations like our mochitests which deal with more complex global situations. Overall, this can allow us to move away from searchfox’s current “soupy” understanding of JS code where it assumes that all the JS it ever sees is running in a single global.
- Python via scip-python (Bug 1426456)
- Java / Kotlin via scip-java (Bug 1490144)
Searchfox’s strongest support is for C++ (and its interactions with XPIDL and IPDL), but there is still more to do here. Thankfully Botond is working to improve C++ template handling in Bug 1781178 and related bugs.
Other enhancements:
- Bug 1419018: Allow distinguishing LHS/RHS usages of fields, with a prototype of relevance in Bug 1733217.
mozilla-central contains a number of Mozilla-specific Interface Definition Languages (IDLs) and Domain Specific Languages (DSLs). Searchfox has existing support for:
- XPIDL .idl files: Our C++ support here is pretty good because XPIDL files are not preprocessed (beyond in-language support of #include and the ability to put pass-through C++ code including preprocessor directives inside %{C++ and %}demarcated blocks. Bug 1761689 tracks adding support for constants/enums which is not currently supported, and I have WIPs for this. Bug 1800008 tracks adding awareness of the rust bindings.
- IPDL .ipdl and .ipdlh files: Our C++ support here is good as long as the file is not pre-processed and the rust IPDL parser hasn’t fallen behind the Python parser. Unfortunately a lot of critical files like PContent.ipdl are pre-processed so this currently creates massive blind-spots in searchfox’s understanding of the system. Bug 1661067 will move us to having the Python parser/code generator emit data searchfox can ingest
Searchfox has planned support for:
- WebIDL .webidl files: Bug 1416899 tracks indexing WebIDL files, and Bug 1525189 tracks the JS interaction side of this.
- StaticPrefList.yaml and related preference bindings: Bug 1699048 with discussion in Bug 1727789 on which it certainly depends.
- Taskcluster Taskgraph files: Bug 1800016.
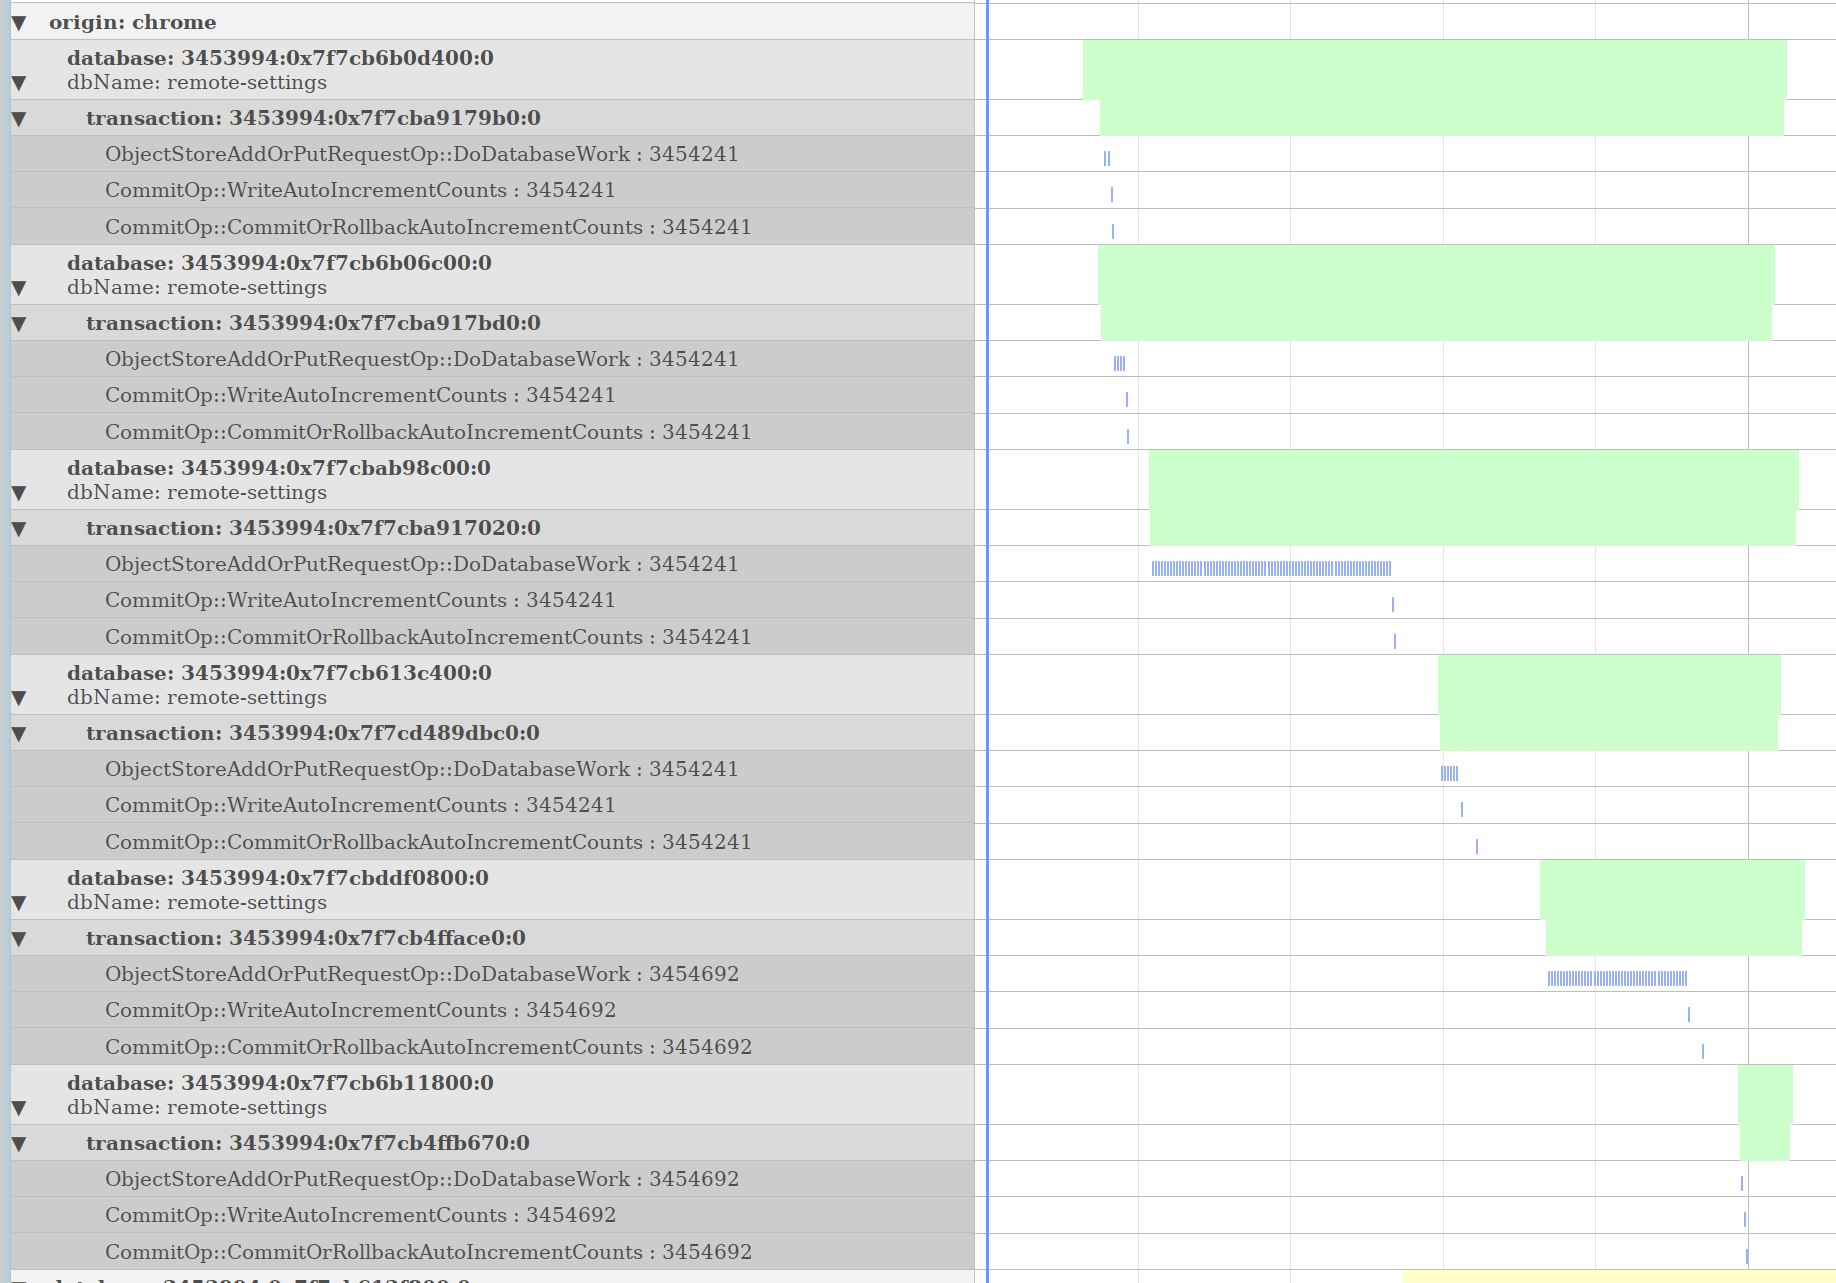 pernosco-bridge IDB timeline visualization
Searchfox’s language indexing is inherently a form of static analysis. Consistent with the searchfox vision saying that “searchfox is not the only tool”, it makes sense to attempt to integrate with and build upon the tools that Firefox engineers are already using. Mozilla’s code-coverage data is already integrated with searchfox, and the next logical step is to integrate with pernosco, why not. I created pernosco-bridge as an experimental means of extracting data from pernosco and allowing for interactive visualizations.
The screenshot above is an example of a timeline graph automatically extracted from a config file to show data relevant to IndexedDB. IndexedDB transactions were hierarchically related to their corresponding database and the origin that opened those databases. Within each transaction, ObjectStoreAddOrPutRequestOp and CommitOp operations are graphed. Clicking on the timeline would direct the pernosco tab to jump to those instants in time.
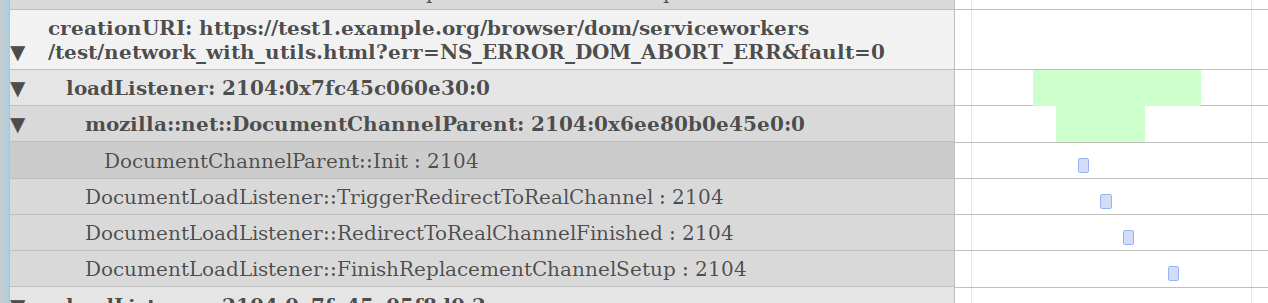 pernosco-bridge DocumentChannel visualization
The above is a different visualization based on a config file for DocumentChannel to help group what’s going on in a pernosco trace and surface the relevant information. If you check out the config file, you will probably find it inscrutable, but with searchfox’s structured understanding of C++ classes landed last year in Bug 1641372 we can imagine leveraging searchfox’s understanding of the codebase to make this process friendly. More importantly, there is the potential to collaboratively build a shared knowledge base of what’s most relevant for classes, so everyone doesn’t need to re-do the same work.
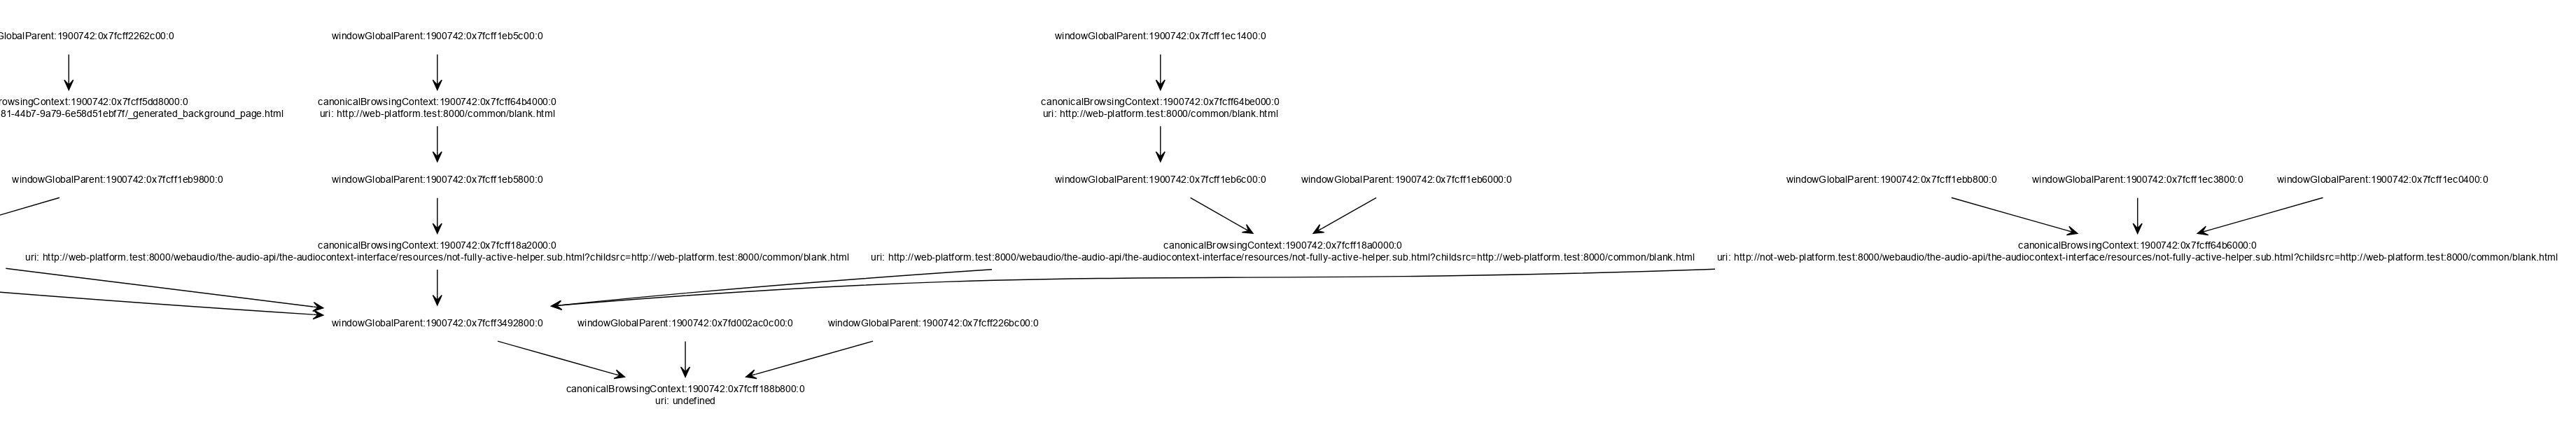
Using the same information pernosco-bridge used to build the hierarchically organized timelines above with extracted values like URIs, it can also build graphs of the live objects at any moment in time in the trace. Above we can see the relationship between windowGlobalParent instances and their corresponding canonicalBrowsingContexts, plus the URIs of the canonicalBrowsingContexts. We can imagine using this to help visualize representative object graphs in searchfox.
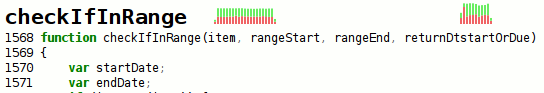
We can also imagine doing something like the above screenshot from my prior experiment pecobro where we interleave graphs of function activity into source listings.
Token-Centric Blame / “hyperannotate” Support via Microannotate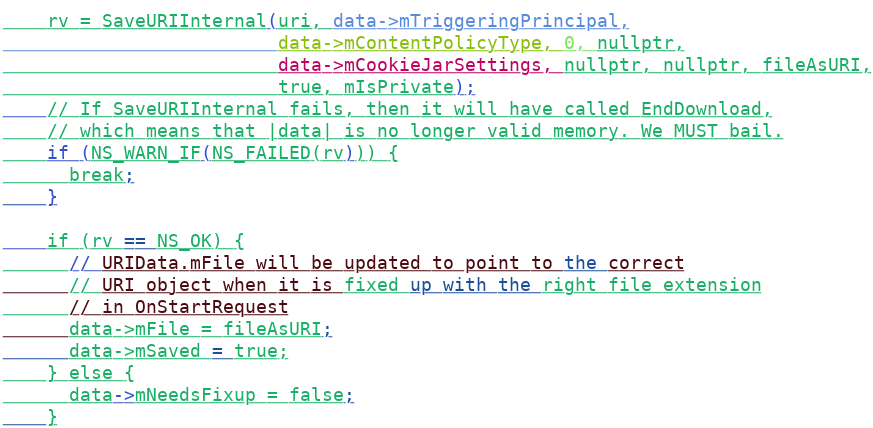 A demonstration of microannotate’s output
Quoting my dev-platform post about the unfortunate removal of searchfox’s first attempt at blame-skipping: “Revision history and the “annotate” / “blame” UIs for revision control are tricky because they’re built on a sequential, line-centric data-model where moving a function above another function in a file results in a destructive representational decision to treat one function as continuing through history and the other function as removed and then re-added as new code. Reformatting that maintains the overall sequence of tokens but changes how they are distributed across multiple lines also looks like removal of all of the old code and the addition of new code. Tools frequently perform heuristic-based post-passes to help identify intra-line changes which are reflected in diff UIs, as well as (entire) lines of code that are copied/moved in a revision (ex: Phabricator does this).”
The plan to move forward is to move to a token-centric approach using :marco‘s microannotate project as tracked in Bug 1517978. We would also likely want to combine this with heuristics that skip over backout pairs. The screenshot at the top of this section is of example output for nsWebBrowserPersist.cpp where colors distinguish between different blame revision origins. Note that the addition of specific arguments can be seen as well as changes to comments.
Source Listings- Bug 1781179: Improved syntax and semantic highlighting in C++ for the tip/head indexed revision.
- Bug 1583635: Show expansion of C++ macros. Do you ever look at our XPCOM macrology and wish you weren’t about to spend several minutes clicking through those macros to understand what’s happening? This bug, my friend, this bug.
- Bug 1796870: Adopt use of tree-sitter as a tokenizer which can improve syntax highlighting for other languages as well as position: sticky context for both the tip/head indexed revision but also for historical revisions!
- Bug 1799557: Improved handling of links to source files that no longer exist by offering to show the last version of the file that existed or try and direct the user to the successor code.
- Bug 1697671: Link resource:// and chrome:// URLs in source listings to the underlying source files
- Test Info Boxes
- Bug 1785129: Add an info box mechanism to indicate the need for data collection review (“data review”) in info boxes on searchfox source listing pages
- Bug 1797855: Joel Maher and friends have been adding all kinds of great test metadata for searchfox to expose, and soon, this bug shall expose that information. Unfortunately there’s some yak shaving related to logging that remains underway.
- Bug 1797857: Extend the “Go to header file”/”Go to source file” mechanism to support WPT `.headers` files and xpcshell/mochitest `^headers^` files.
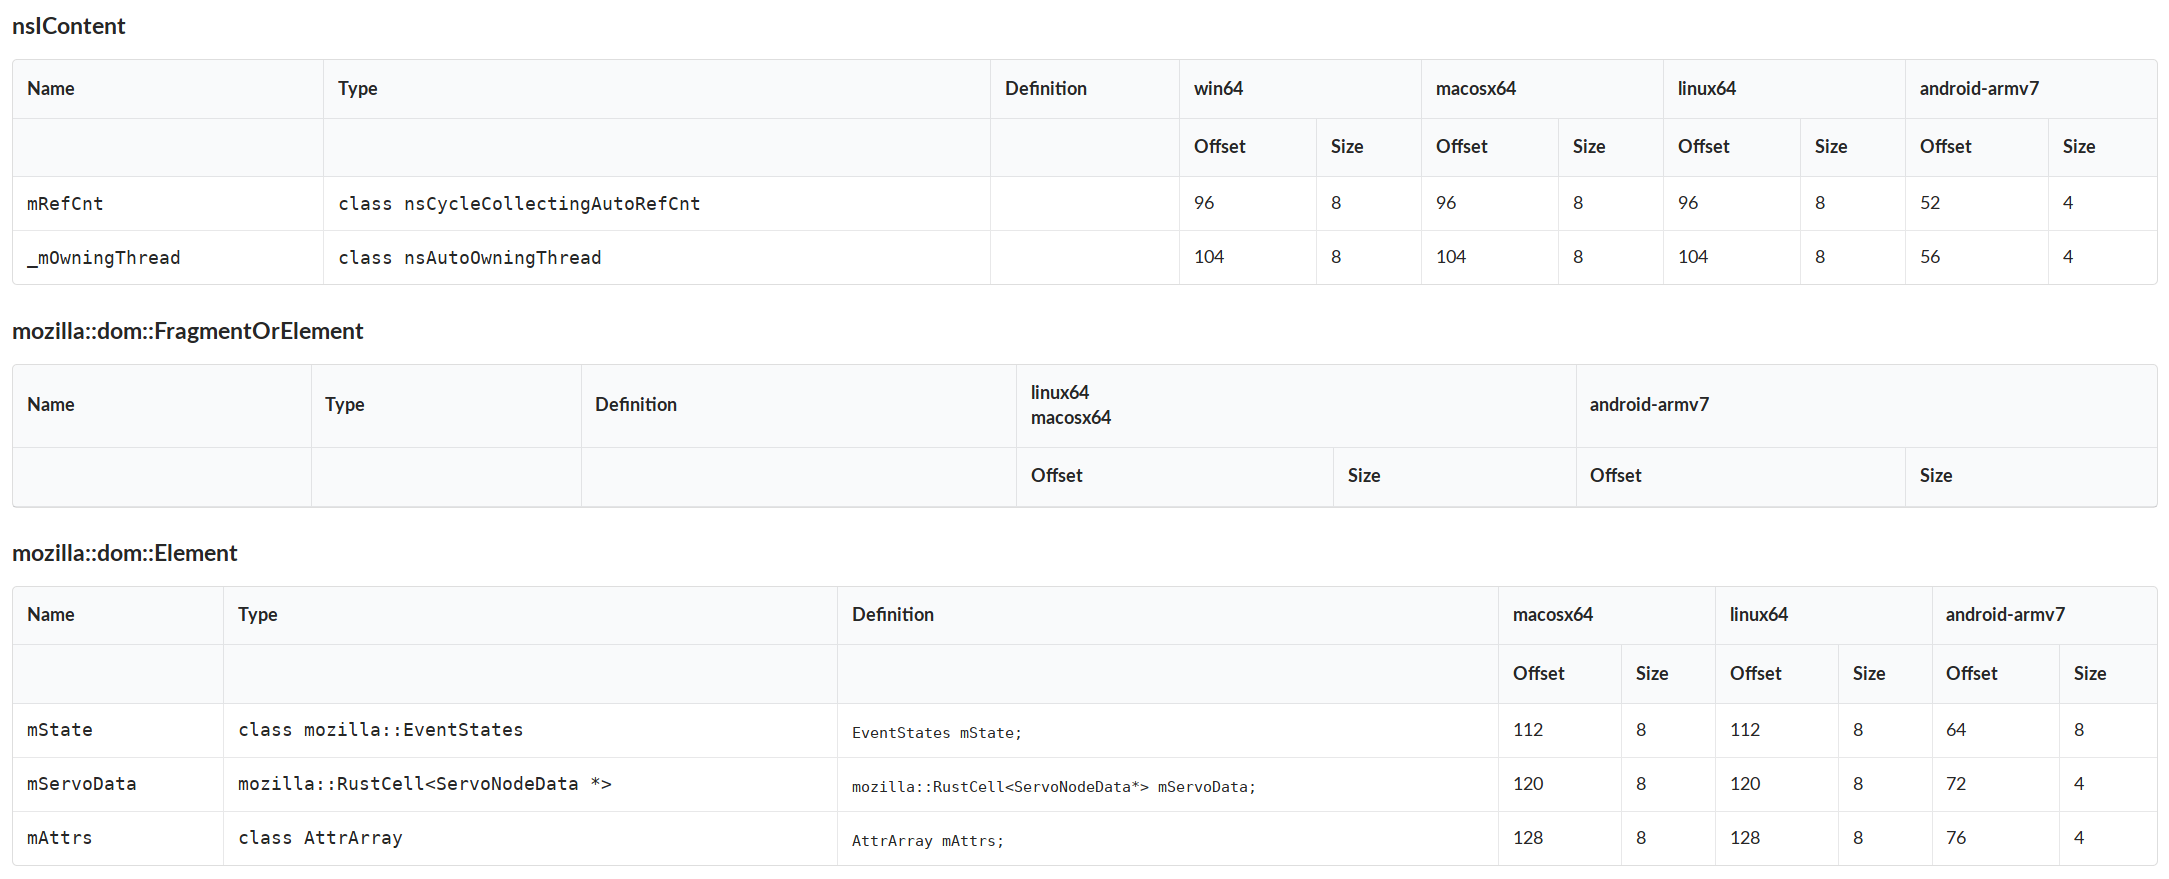
Searchfox is able to provide more than source listings. The above screenshot shows searchfox’s understanding of the field layouts of C++ classes across all the platforms searchfox indexes on as rendered by the “fancy” branch prototype. Bug 1468445 tracks implementing a production quality version of this, noting that the data is already available, so this is straightforward. Bug 1799517 is a variation on this which would help us explicitly capture the destructor order of C++ fields.
Bug 1672307 tracks showing the binary size impact of a given file, class, etc.
Source Directory ListingsIn the recently landed Bug 1783761 I moved our directory listings into rust after shaving a whole bunch of yaks. Now we can do a bunch of queries on data about files. Would you like to see all the tests that are disabled in your components? We could do this! Would you like to see all the files in your components that have been modified in the last month but have bad coverage? We could also do that! There are many possibilities here but I haven’t filed bugs for them.
- Bug 1543707: Add README.md support to directories
- Bug 1732585: Provide a way to search related (phabricator revision) review/bugzilla comments related to the current file
- Bug 1657786: Create searchfox taskcluster mode/variant that can run the C++ indexer only against changed files for try builds / phabricator requests
- Bug 1778802: Consider storing m-c analysis data in a git repo artifact with a bounded history via `git checkout –orphan` to enable try branch/code review features and recent semantic history support
The largest hurdle new contributors have faced is standing up a virtual machine. In Bug 1612525 we’ve added core support for docker, and we have additional work to do in that bug to document using docker and add additional support for using docker under WSL2 on Windows. Please feel free to drop by https://chat.mozilla.org/#/room/#searchfox:mozilla.org if you need help getting started.
Deeper Integration with Mozilla InfrastructureCurrently much of searchfox runs as EC2 jobs that exists outside of taskcluster, although C++ and rust indexing artifacts as well as all coverage data and test info data comes from taskcluster. Bug 1598502 tracks moving more of searchfox into taskcluster, although presumably the web-servers will still need to exist outside of taskcluster.
Andrew Sutherland: Andrew’s Searchfox Vision 2022
Searchfox (source, config source) is Mozilla’s primary code searching tool for Firefox introduced by Bill McCloskey in 2016 which built upon prior work on DXR. This product vision post describes my personal vision for searchfox and the rationale that underpins it. I’m also writing an accompanying road map that describes specific potential enhancements in support of this vision which I will publish soon and goes into the concrete potential features that would be implemented in the spirit of this vision.
Note that the process of developing searchfox is iterative and done in consultation with its users and other contributors, primarily in the searchfox channel on chat.mozilla.org and in its bugzilla component. Accordingly, these documents should be viewed as a basis for discussion rather than a strict project plan.
The Whys Of Searchfox Searchfox is a Tool For System UnderstandingSearchfox enables exploration and understanding of the Firefox codebase as it exists now, as it existed in the past, and to support understanding of the ramifications of potential changes.
Searchfox Is A Tool For Shared System UnderstandingFirefox is a complex piece of software which has more going on than any one person can understand at a time. Searchfox enables Firefox’s contributors to leverage the documentation artifacts of other teams and contributors when exploring in isolation, and to communicate more effectively when interacting.
Searchfox Is Not The Only ToolSearchfox integrates relevant data from automation and other tools in the Firefox development ecosystem where they make sense and provides deep links into those tools or first steps to help you get started without having to start from nothing.
The Hows Of Searchfox Searchfox is Immediate: Low Latency and CompleteSearchfox’s results should be available in their entirety when the page load completes, ideally in much less than a second. There should be no asynchronous lazy loading or spinners. Practically speaking, if you could potentially see something on a page, you should be able to ctrl-f for it.
In situations where results are too voluminous to be practically useful, Searchfox should offer targeted follow-on searches that can relax limits and optionally provide for additional constraints so that iterative progress is made.
Searchfox is AccessibleSearchfox should always present a usable accessibility tree. This includes ensuring that any dynamically generated graphical representations such as graphviz-style diagrams have a directly usable accessibility tree or an alternate representation that maximally captures any hierarchy or clustering present in the visual presentation.
Searchfox Favors Iterative Exploration and Low Activation EnergySearchfox seeks to avoid UX patterns where you have to metaphorically start from a blank sheet of paper or face decision paralysis choosing among a long list of options. Instead, start from whatever needle you have (an identifier name, a source file location, a string you saw in the UI) and searchfox will help you iterate and refine from there.
Searchfox Provides Stable, Useful URLs When Possible and Markdown For More Complex SituationsIf you’re looking at something in searchfox, you should be able to share it as a URL, although there may be a few URLs to choose from such as whether to use a permalink which includes a specific revision identifier. More complicated situations may merit searchfox providing you with markdown that you can paste in tools that understand markdown.
Robert Kaiser: Connecting the Mozilla Community
Following the talk, I brought that topic to the Reps Weekly Call this last week (see linked video), esp. focusing on one slide from my FOSDEM talk that talks about finding some kind of communication channel to cross-connect the community. As Reps are already a somewhat cross-function community group, my hope is that a push from that direction can help getting such a channel in place - and figuring out what exactly is a good idea and doable with the resources we have available (I for example like the idea of a podcast as I like how those can be listened to while traveling, cooking, doing house work, and others things - but it would be a ton of work to organize and produce that).
Some ideas that came up in the Reps Call were for example a regular newsletter on Mozilla Discourse in the style of the MoCo-internal "tl;dr" (which Reps have access to via NDA), but as something that is public, as well as from and for the community - or maybe morphing some Reps Calls regularly into some sort of "Community News" calls that would highlight activities around the wider community, even bringing in people from those various projects/efforts there. But there may be more, maybe even better ideas out there.
To get this effort to the next level, we agreed that we'll first get the discussion rolling on a Discourse thread that I started after the meeting and then probably do a brainstorming video call. Then we'll take all that input and actually start experimenting with the formats that sound good and are practically achievable, to find what works for us the best way.
If you have ideas or other input on this, please join the conversation on Discourse - and also let us know if you can help in some form!
Robert Kaiser: Is Mozilla Still Needed Nowadays?
Here's a bit more rambling on this topic...
First of all, the Mozilla project was officially started on March 31, 1998, which is 23 years ago today. Happy birthday to my favorite "dino" out there! For more background, take a look at my Mozilla History talk from this year's FOSDEM, and/or watch the "Code Rush" documentary that conserved that moment in time so well and also gives nice insight into late-90's Silicon Valley culture.
Now, while Mozilla initially was there to "act as the virtual meeting place for the Mozilla code" as Netscape was still there with the target to win back the browser market that was slipping over to Micosoft. The revolutionary stance to develop a large consumer application in the open along with the marketing of "hack - this technology could fall into the right hands" as well as the general novenly of the open-source movement back then - and last not least a very friendly community (as I could find out myself) made this young project grow fast to be more than a development vehicle for AOL/Netscape, though. And in 2003, a mission to "preserve choice and innovation on the Internet" was set up for the project, shortly after backed by a non-profit Mozilla Foundation, and then with an independently developed Firefox browser, implementing "the idea [...] to design the best web browser for most people" - and starting to take back the web from the stagnation and lack of choice represented by >95% of the landscape being dominated by Microsoft Internet Explorer.
The exact phrasing of Mozilla's mission has been massages a few times, but from the view of the core contributors, it always meant the same thing, it currently reads:Quote:Our mission is to ensure the Internet is a global public resource, open and accessible to all. An Internet that truly puts people first, where individuals can shape their own experience and are empowered, safe and independent.On the Foundation site, there's the sentence "It is Mozilla’s duty to ensure the internet remains a force for good." - also pretty much meaning the same thing with that, just in less specific terms. Of course, the spirit of the project was also put into 10 pretty concrete technical principles, prefaced by 4 social pledges, in the Mozilla Manifesto, which make it even more clear and concrete what the project sees as its core purpose.
So, if we think about the question whether we still need Mozilla nowadays, we should take a look if moving in that direction is still required and helpful, and if Mozilla is still able and willing to push those principles forward.
When quite a few communities I'm part of - or would like to be part of - are moving to Discord or are adding it as an additional option to Facebook groups, and I read the Terms of Services of those two tightly closed and privacy-unfriendly services, I have to conclude that the current Internet is not open, not putting people first, and I don't feel neither empowered, safe or independent in that space. When YouTube selects recommendations so I live in a weird bubble that pulls me into conspiracies and negativity pretty fast, I don't feel like individuals can shape their own experience. When watching videos stored on certain sites is cheaper or less throttled than other sources with any new data plan I can get for my phone, or when geoblocking hinders me from watching even a trailer of my favorite series, I don't feel like the Internet is equally accessible to all. Neither do I when political misinformation is targeted at certain groups of users in election ads on social networks without any transparency to the public. But I would long for that all to be different, and to follow the principles I talked of above. So, I'd say those are still required, and would be helpful to push for.
It all feels like we need someone to unfck the Internet right now more than ever. We need someone to collect info on what's wrong and how it could get better there. We need someone to educate users, companies and politicians alike on where the dangers are and how we can improve the digital space. We need someone who gives us a fast, private and secure alternative to Google's browser and rendering engine that dominates the Internet now, someone to lead us out of the monoculture that threatens to bring innovation to a grind. Someone who has protecting privacy of people as one of their primary principles, and continues work on additional ways of keeping people safe. And that's just the start. As the links on all those points show, Mozilla tries hard to do all that, and more.
I definitely think we badly need a Mozilla that works on all those issues, and we need a whole lot of other projects and people help in the space as well. Be it in advocacy, in communication, in technology (links are just examples), or in other topics.
Can all that actually succeed in improving the Internet? Well, it definitely needs all of us to help, starting with using products like Firefox, supporting organizations like Mozilla, spreading the word, maybe helping to build a community, or even to contribute where we can.
We definitely need Mozilla today, even 23 years after its inception. Maybe we need it more than ever, actually. Are you in?
 The text of this post is licensed under Creative Commons BY-SA 4.0.
Robert Kaiser: Crypto stamp Collections - An Overview
We set off to find existing standards on Ethereum contracts for grouping NFTs (ERC-721 and potentially ERC-1155 tokens) together and we found that there are a few possibilities (like EIP-998) but those ares getting complicated very fast. We wanted a collection (a stamp album) to actually be the owner of those NFTs or "assets" but at the same time being owned by an Ethereum account and able to be transferred (or traded) as an NFT by itself. So, for the former (being the owner of assets), it needs to be an Ethereum account (in this case, a contract) and for the latter (being owned and traded) be a single ERC-721 NFT as well. The Ethereum account should not be shared with other collections so ownership of an asset is as transparent as people and (distributed) apps expect. Also, we wanted to be able to give names to collections (via ENS) so it would be easier to work with them for normal users - and that also requires every collection to have a distinct Ethereum account address (which the before-mentioned EIP-998 is unable to do, for example). That said, to be NFTs themselves, the collections need to be "indexed" by what we could call a "registry of Collections".
To achieve all that, we came up with a system that we think could be a model for future similar project as well and would ideally form the basis of a future standard itself.
Now this Collection contract is the account that receives ERC-721 and ERC-1155 assets, and becomes their owner. It also does some bookkeeping so it can actually be queried for assets and has functionality so the owner of the Collection's own NFT (the actual owner of the Collection itself) and full control over those assets, including functions to safely transfer those away again or even call functions on other contracts in the name of the Collection (similar to what you would see on e.g. multisig wallets).
As the owner of the Collection's NFT in the "registry" contract ("Collections") is the one that has power over all functionality of this Collection contract (and therefore the assets it owns), just transferring ownership of that NFT via a normal ERC-721 transfer can give a different person control, and therefore a single trade can move a whole collection of assets to a new owner, just like handing a full album of stamps physically to a different person.
To go into more details, you can look up the code of our Collections contract on Etherscan. You'll find that it exposes an ERC-721 name of "Crypto stamp Collections" with a symbol of "CSC" for the NFTs. The collections are registered as NFTs in this contract, so there's also an Etherscan Token Tracker for it, and as of writing this post, over 1600 collections are listed there. The contract lets anyone create new collections, and optionally hand over a "notification contract" address and data for registering an ENS name. When doing that, a new Collection contract is deployed and an NFT minted - but the contract deployment is done with a twist: As deploying a lot of full contracts with a larger set of code is costly, an EIP-1167 minimal proxy contract is deployed instead, which is able to hold all the data for the specific collection while calling all its code via proxying to - in this case - our Collection Prototype contract. This makes creating a new Collection contract as cheap as possible in terms of gas cost while still giving the user a good amount of functionality. Thankfully, Etherscan for example has knowledge of those minimal proxy contracts and even can show you their "read/write contract" UI with the actually available functionality - and additionally they know ENS names as well, so you can go to e.g. etherscan.io/address/kairo.c.cryptostamp.eth and read the code and data of my own collection contract. For connecting that Collection contract with its own NFT, the Collections (CSC) contract could have a translation table between token IDs and contract addresses, but we even went a step further and just set the token ID to the integer value of the address itself - as an Ethereum address is a 40-byte hexadecimal value, this results in large integer numbers (like 675946817706768216998960957837194760936536071597 for mine) but as Ethereum uses 256-bit values by default anyhow, it works perfectly well and no translation table between IDs and addresses is needed. We still do have explicit functions on the main Collections (CSC) contract to get from token IDs to addresses and vice versa, though, even if in our case, it can be calculated directly in both ways.
Both the proxy contract pattern and the address-to-token-ID conversion scheme are optimizations we are using but if we were to standardize collections, those would not be in the core standard but instead to be recommended implementation practices instead.
For showing contents or calculating such a "fingerprint", there needs to be a way to find out, which assets the collection actually owns. There are three ways to do that in theory: 1) Have a list of all assets you care about, and look up if the collection address is listed as their owner, 2) look at the complete event log on the blockchain since creation of the collection and filter all NFT Transfer events for ones going to the collection address or away from it, or 3) have some way of so the collection itself can record what assets it owns and allow enumeration of that. Option 1 is working well as long as your use case only covers a small amount of different NFT contracts, as e.g. the Crypto stamp website is doing right now. Option 2 gives general results and is actually pretty feasible with the functionality existing in the Ethereum tool set, but it requires a full node and is somewhat slow.
So, for allowing general usage with decent performance, we actually implemented everything needed for option 3 in the collections contract. Any "safe transfer" of ERC-721 or ERC-1155 tokens (e.g. via a call to the safeTransferFrom() function) - which is the normal way that those are transferred between owners - does actually test if the new owner is a simple account or a contract, and if it actually is a contract, it "asks" if that contract can receive tokens via a contract function call. The collection contract does use that function call to register any such transfer into the collection and puts such received assets into a list. As for transferring away an asset, you need to make a function call on the collection contract anyhow, removing from that list can be done there. So, this list can be made available for querying and will always be accurate - as long as "safe" transfers are used. Unfortunately, ERC-721 allows "unsafe" transfers via transferFrom() even though it warns that NFTs "MAY BE PERMANENTLY LOST" when that function is used. This was probably added into the standard mostly for compatibility with CryptoKitties, which predate this standard and only supported "unsafe" transfers. To deal with that, the collections contract has a function to "sync" ownership, which is given a contract address and token ID, and it adjusts it assets list accordingly by either adding or removing it from there. Note that there is a theoretical possibility to also lose an assets without being able to track it there, that's why both directions are supported there. (Note: OpenSea has used "unsafe" transfers in their "gift" functionality at least in the past, but that hopefully has been fixed by now.)
So, when using "safe" transfers or - when "unsafe" ones are used - "syncing" afterwards, we can query the collection for its owned assets and list those in a generic way, no matter which ERC-721 or ERC-1155 assets are sent to it. As usual, any additional data and meta data of those assets can then be retrieved via their NFT contracts and their meta data URLs.
One thing I also mentioned before is that the owner of a Collection can actually call functions in other contracts in the name of the Collection, similar to functionality that multisig wallets provide. This is done via an externalCall() function, to which the caller needs to hand over a contract address to call and an encoded payload (which can relatively easily be generated e.g. via the web3.js library). The result is that the Collection can e.g. call the function for Crypto stamps sold via the OnChain shop to have their physical versions sent to a postage address, which is a function that only the owner of a Crypto stamp can call - as the Collection is that owner and its own owner can call this "external" function, things like this can still be achieved.
To conclude, with Crypto stamp Collections we have created a simple but feature-rich solution to bring the experience of physical stamp albums to the digital world, and we see a good possibility to use the same concept generally for collecting NFTs and enabling a whole such collection of NFTs to be transferred or traded easily as one unit. And after all, NFT collectors would probably expect a collection of NFTs or a "stamp album" to have its own NFT, right? I hope we can push this concept to larger adoption in the future!